



The post has been translated automatically. Original language: Russian



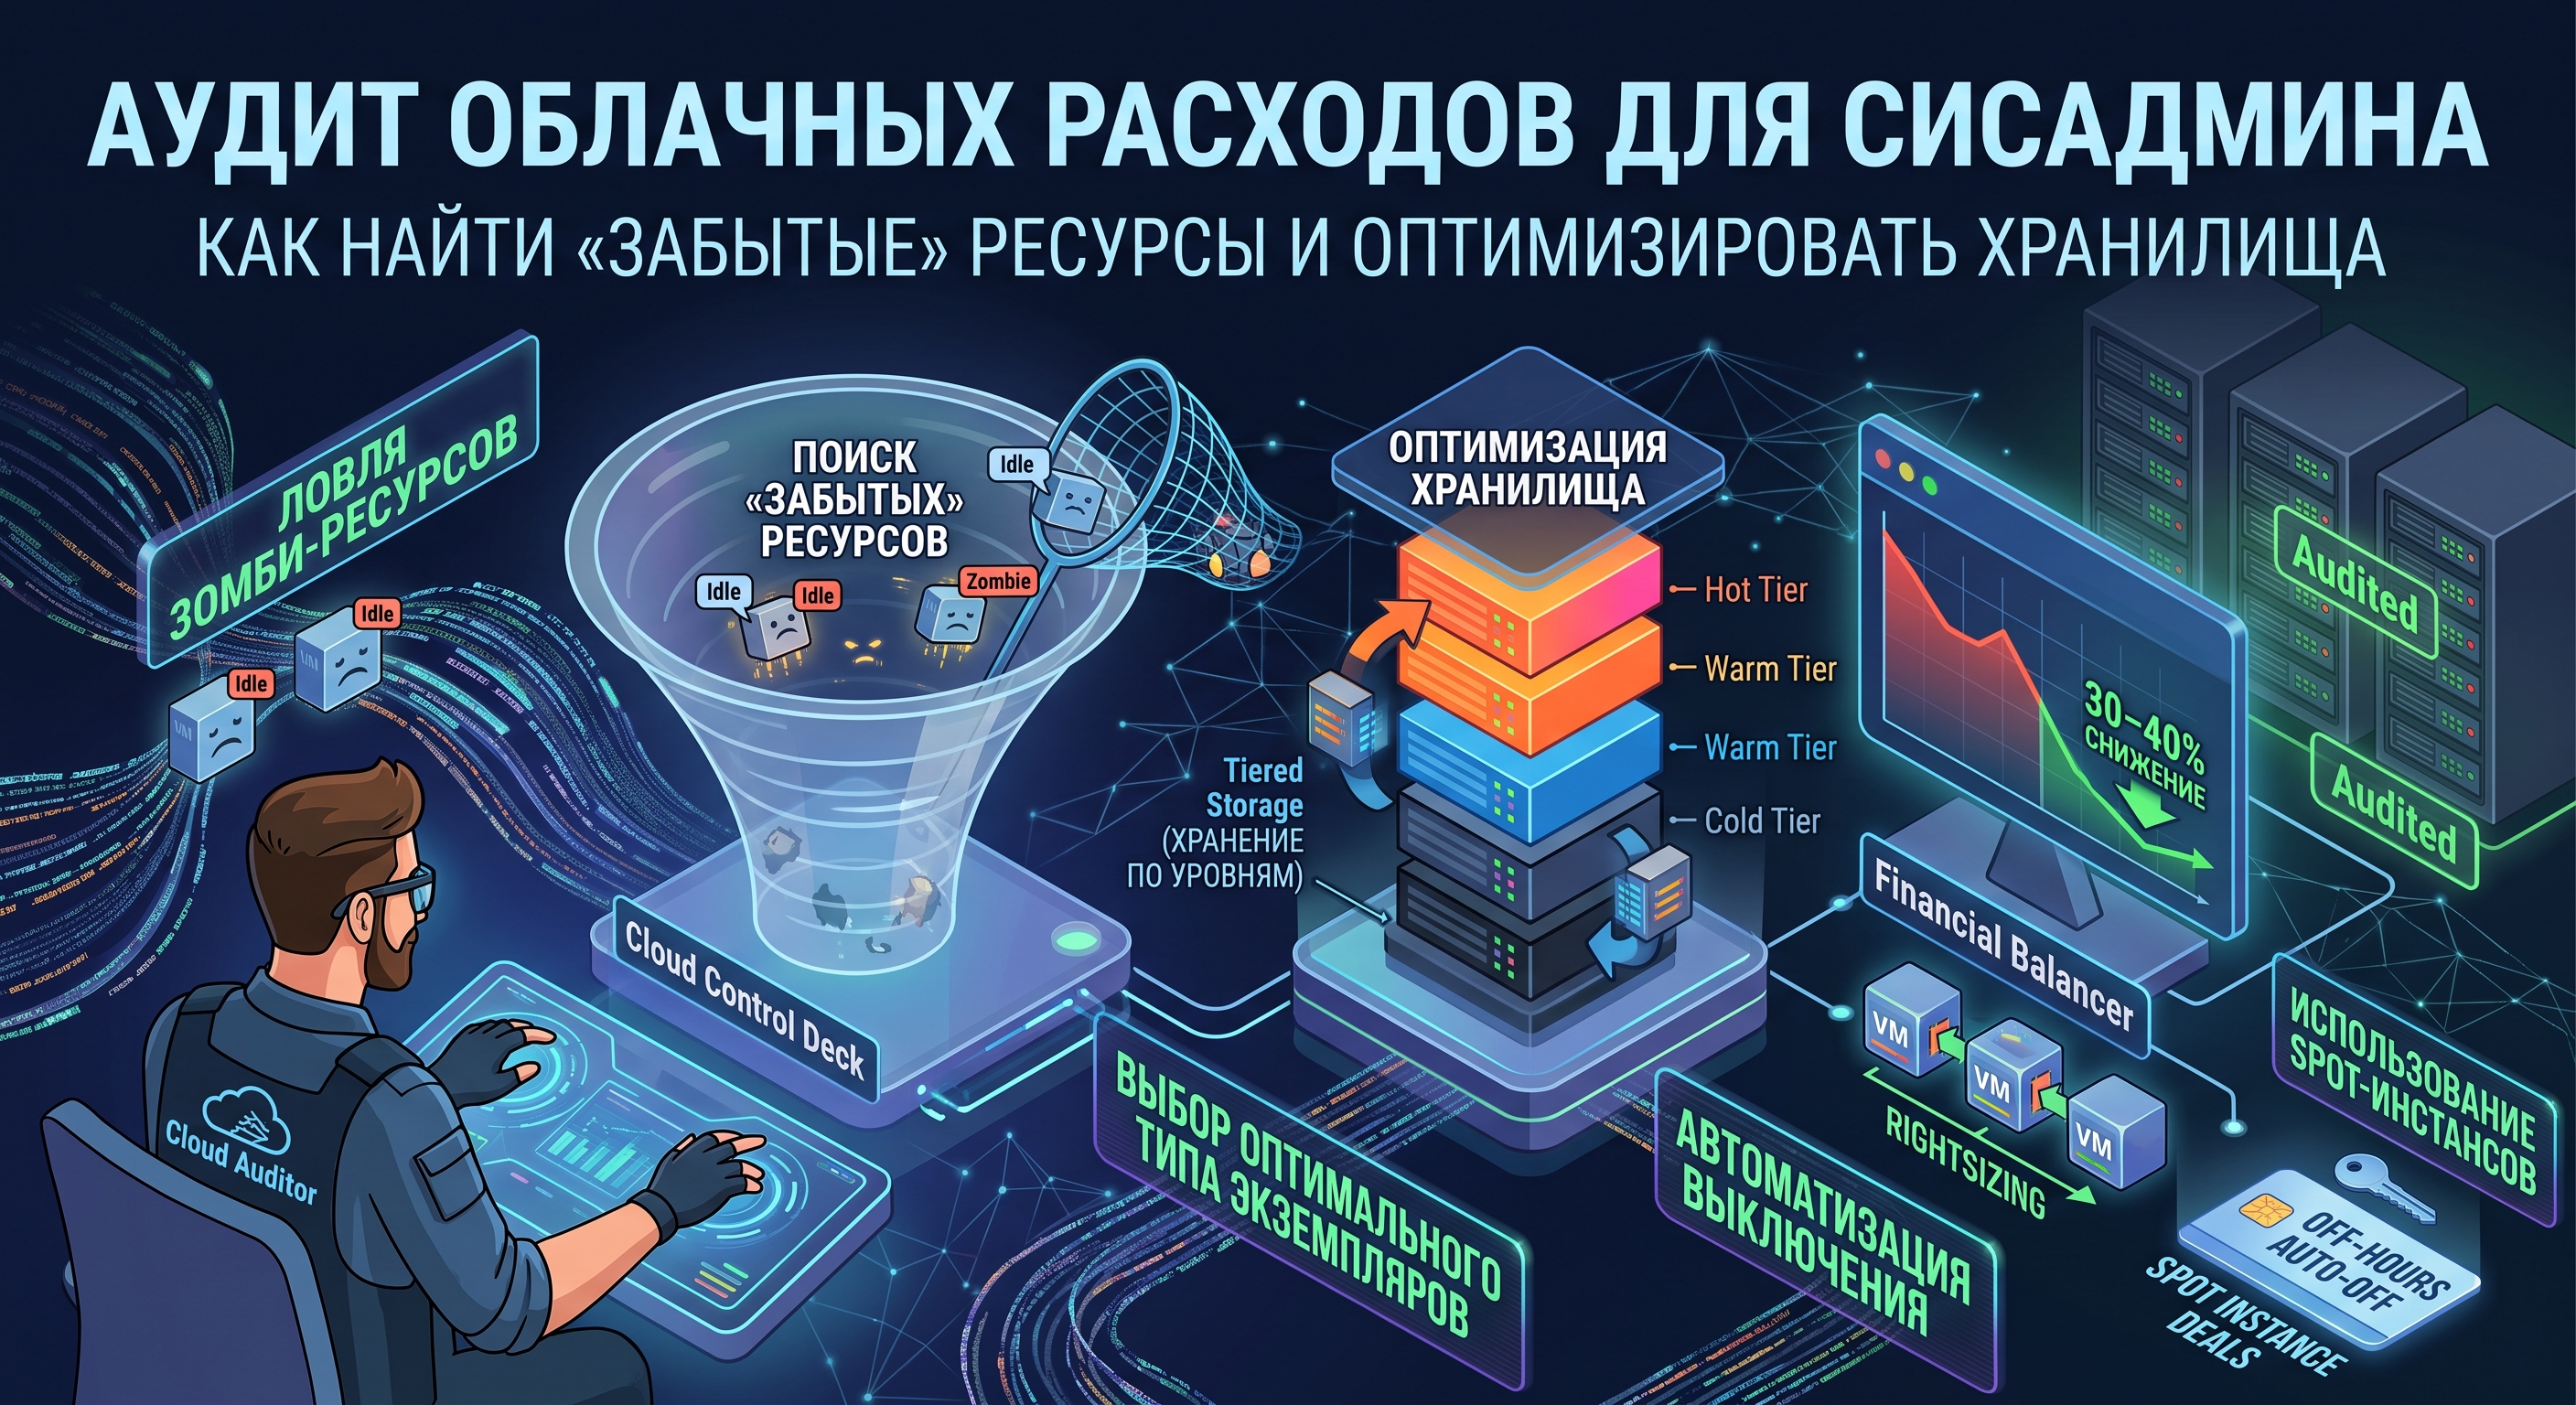
Cloud expense audit for a sysadmin: how to find "forgotten" resources, optimize storage and reduce the bill for the cloud by 30-40%
The "raised the virtual machine and forgot" approach is costing the company too much in the cloud era. Unlike our own Bare Metal servers, where the idle hardware has already been paid for, a counter is ticking in the cloud for every extra gigabyte and reserved IP address.
Engineers usually focus on availability (Uptime) and performance, leaving billing to management. However, it is the system administrator who has direct access to the infrastructure and sees where the money goes into the "black hole". We are figuring out how to audit the cloud and reduce the receipt by 30-40% without compromising stability.
1. Search for "zombie resources": Delete what no one uses
The first and fastest stage of optimization is the search for resources that continue to be charged, although they are not actually used.
Audit of "Zombie resources"
| Orphaned Disks / Volumes | Disks from remote instances |
| Unattached Elastic IPs | Unbound public IP addresses |
| Forgotten Snapshots | Old manual backups |
| Orphaned Load Balancers | Load balancers without targets |
What to pay attention to first:
- Orphaned disks (Orphaned EBS / Cloud Disks): When deleting a VM (AWS EC2, Yandex Compute Cloud, VK Cloud), the attached additional disks often remain intact. You keep paying for gigabytes and guaranteed IOPS for a disk that no one accesses.
- What to do: Filter the disks with the available/unattended status and create a script that deletes them after taking the final snapshot.
- Unbound Public IP addresses (Static/Elastic IPs): Cloud providers charge for reserved static IP addresses that are not linked to running instances or load balancers.
- What to do: Identify unused addresses and release them via the CLI/Console.
- Abandoned Load Balancers (ALB / NLB): Load balancers are charged for the very fact of their existence + for the amount of traffic that has passed. If the Target Group is empty or the services behind it have been decommissioned for a long time, ALB continues to burn the budget.
- Single snapshots and old images (AMIs / Custom Images): Manual snapshots taken before the "critical update three months ago" accumulate in gigabytes.
- What to do: Set up automatic Lifecycle Policies for backups with a tight TTL (for example, store for 14 days).
2. Storage Optimization: Disks and Object Storage (S3)
Data storage is one of the fastest growing items of expenditure. Engineers often choose the most expensive type of disk "just in case."
A. Changing the types of block disks (Block Storage)
In AWS, switching from gp2 to gp3 provides instant savings of about 20% with the same or better performance. It's the same in other clouds: not all services need expensive NVMe/High-Performance SSDs.
- Ultra/High-Speed SSDs: Only needed for high-load databases (PostgreSQL, ClickHouse).
- Standard SSD: Suitable for most web servers and applications.
- HDD / Cold Storage: Ideal for logs, archives and rare backups.
B. Data lifecycle in S3 (Lifecycle Rules)
In S3 storage, gigabytes accumulate unnoticeably. The main mistake is to store everything in the Standard class, namely:
- S3 Standard (Active Data)
- S3 Standard-IA / Infrequent Access (after 30 days)
- S3 Glacier / Cold Storage (Archive) (after 90 days)
- Deletion (Expiration) (after 365 days)
Configure S3 Lifecycle Rules to automate the transfer of old logs and backups to "cold" storage classes. This reduces the cost of storing a gigabyte by 3-5 times.
3. RightSizing and automation of environments
Many virtual machines are idle, consuming only 5-10% of the CPU.
A. RightSizing
Analyze the metrics for the last 30 days (CloudWatch, Prometheus, Yandex Monitoring). If the average CPU utilization of an instance does not exceed 15%, and the peak utilization does not exceed 40%, feel free to reduce the instance size by one step (for example, from xlarge to large).
B. Shutting down non-production environments (Dev/Stage)
Developers and testers do not need Dev and Stage booths at night and on weekends.
- Automation: Set up Cron scripts, Lambda/Cloud Functions, or Kubernetes operators (for example, Kube-downscaler) that stop VMs and scale deployments to 0 at 20:00 and raise them at 08:00 on weekdays.
- Effect : Turning off the Dev environment at night and on weekends reduces its operating time from 720 hours to ~180 hours per month (saving up to 75% on these resources).
4. Procurement Strategies: Spot/Preemptible and Reserved / Commitments
Providers offer different financial payment models for resources:
Payment models in the cloud
| On-Demand / PAYG | As expensive and flexible as possible (per second) |
| Reserved / Savings | 30-60% discount for a 1-3-year contract |
| Spot / Preemptible | 70-90% discount (can be picked up at any time) |
- Spot / Preemptible instances: Unclaimed provider capacities that are sold at a huge discount (up to 80-90%), but can be recalled with a warning in 30-120 seconds.
- Where to use: Queue workers (Celery, RabbitMQ), K8s nodes for stateless applications, test environments, CI/CD runners.
- Reserved Instances / Savings Plans / Committed Use: If you have a base load (databases, production servers) that will definitely last for the next year, make a reservation. This gives you a direct discount of 30-50% without having to change the architecture.
5. Combating Egress traffic (Outbound traffic)
Outbound traffic from the cloud to the Internet or between regions often comes as a surprise at the end of the month.
- Use VPC Endpoints / Internal Traffic: Traffic between your Compute instance and S3 over the public Internet is charged. Using internal routing (VPC Endpoints) reduces latency and zeroes/reduces traffic costs.
- CDN for static: Distributing media files and static directly from S3 is expensive. Connecting CDNs (CloudFront, Cloudflare, Fastly) significantly reduces the cost of giving a gigabyte to a user.
- Compression: Enable gSOAP/gzip/brotli at the Nginx/Ingress level to reduce the amount of data transferred.
Audit sprint checklist for the sysadmin
Set aside 2-3 days for the initial audit and follow the following algorithm:
- Day 1: Cleaning. Find and delete unlinked EBS disks, unused IP addresses, orphaned load balancers, and outdated snapshots.
- Day 2: Storage and Network. Configure S3 Lifecycle Rules for logs and backups. Check the transitions to new disk types (for example, gp3).
- Day 3: Sizes and Schedule. Make downsizing of underloaded VMs. Set up Dev/Stage auto-shutdown for the night.
- Day 4: Finance. Transfer the stateless loads to Spot instances, and reserve the permanent Production (Savings Plan).
Result
Cloud expense audit is not a one—time action, but a regular process (FinOps). The introduction of banal hygiene rules, automation of the removal of "garbage" and the correct choice of types of resource purchases consistently cut off 30-40% of the monthly bill, turning the sysadmin into the eyes of the management from the "cost center" into an effective engineer.
Аудит облачных расходов для сисадмина: как найти «забытые» ресурсы, оптимизировать хранилища и снизить чек за облако на 30–40%
Подход «поднял виртуалку и забыл» в эпоху облаков стоит компании слишком дорого. В отличие от собственных серверов (Bare Metal), где простаивающее железо уже оплачено, в облаке за каждый лишний гигабайт и зарезервированный IP-адрес тикает счетчик.
Обычно инженеры фокусируются на доступности (Uptime) и производительности, оставляя биллинг руководству. Однако именно системный администратор имеет прямой доступ к инфраструктуре и видит, где деньги уходят в «черную дыру». Разбираемся, как провести аудит облака и сократить чек на 30–40% без ущерба для стабильности.
1. Поиск «зомби-ресурсов»: Удаляем то, чем никто не пользуется
Первый и самый быстрый этап оптимизации — поиск ресурсов, которые продолжают тарифицироваться, хотя фактически не используются.
Аудит "Зомби-ресурсов"
| Orphaned Disks / Volumes | Диски от удаленных инстансов |
| Unattached Elastic IPs | Непривязанные публичные IP |
| Forgotten Snapshots | Старые ручные бэкапы |
| Orphaned Load Balancers | Балансировщики без таргетов |
На что обратить внимание в первую очередь:
- Осиротевшие диски (Orphaned EBS / Cloud Disks): При удалении виртуальной машины (AWS EC2, Yandex Compute Cloud, VK Cloud) подключенные дополнительные диски часто остаются целехонькими. Вы продолжаете платить за гигабайты и гарантированные IOPS для диска, к которому никто не обращается.
- Что делать: Отфильтруйте диски со статусом available / unattached и создайте скрипт, удаляющий их после снятия финального снапшота.
- Непривязанные публичные IP-адреса (Static / Elastic IPs): Облачные провайдеры берут плату за зарезервированные статические IP, которые не привязаны к работающим инстансам или балансировщикам.
- Что делать: Выявите неиспользуемые адреса и освободите их через CLI/Console.
- Заброшенные балансировщики (Load Balancers / ALB / NLB): Балансировщики тарифицируются за сам факт существования + за объем прошедшего трафика. Если целевая группа (Target Group) пуста или сервисы за ним давно списаны, ALB продолжает сжигать бюджет.
- Одиночные снапшоты и старые образы (AMIs / Custom Images): Ручные снапшоты, сделанные перед «критическим обновлением три месяца назад», накапливаются гигабайтами.
- Что делать: Настройте автоматические Lifecycle Policies для бэкапов с жестким TTL (например, хранить 14 дней).
2. Оптимизация хранилищ: Диски и Object Storage (S3)
Хранение данных — одна из самых быстрорастущих статей расходов. Часто инженеры выбирают самый дорогой тип диска «на всякий случай».
А. Смена типов блочных дисков (Block Storage)
В AWS переход с gp2 на gp3 дает моментальную экономию около 20% при той же или лучшей производительности. Аналогично в других облаках: не всем сервисам нужны дорогостоящие NVMe / High-Performance SSD.
- Ultra / High-Speed SSD: Нужны только для высоконагруженных СУБД (PostgreSQL, ClickHouse).
- Standard SSD: Подойдут для большинства веб-серверов и приложений.
- HDD / Cold Storage: Идеально для логов, архивов и редких бэкапов.
Б. Жизненный цикл данных в S3 (Lifecycle Rules)
В S3-хранилищах гигабайты накапливаются незаметно. Главная ошибка — хранить всё в классе Standard, а именно:
- S3 Standard (Активные данные)
- S3 Standard-IA / Infrequent Access (Редкий доступ) (через 30 дней)
- S3 Glacier / Cold Storage (Архив) (через 90 дней)
- Удаление (Expiration) (через 365 дней)
Настройте S3 Lifecycle Rules, чтобы автоматизировать перемещение старых логов и бэкапов в «холодные» классы хранения. Это снижает стоимость хранения гигабайта в 3–5 раз.
3. Райтсайзинг (RightSizing) и автоматизация окружений
Многие виртуальные машины простаивают, потребляя лишь 5–10% CPU.
А. Райтсайзинг (RightSizing)
Проанализируйте метрики за последние 30 дней (CloudWatch, Prometheus, Yandex Monitoring). Если средняя утилизация CPU инстанса не превышает 15%, а пиковая не выходит за 40% — смело уменьшайте размер инстанса на одну ступень (например, с xlarge до large).
Б. Выключение непроизводственных окружений (Dev / Stage)
Разработчикам и тестировщикам не нужны Dev- и Stage-стенды ночью и по выходным.
- Автоматизация: Настройте Cron-скрипты, Lambda/Cloud Functions или Kubernetes-операторы (например, Kube-downscaler), которые останавливают виртуальные машины и масштабируют deployment'ы в 0 в 20:00 и поднимают их в 08:00 по рабочим дням.
- Эффект: Выключение Dev-окружения на ночь и выходные снижает время его работы со 720 часов до ~180 часов в месяц (экономия до 75% на этих ресурсах).
4. Стратегии закупки: Spot / Preemptible и Reserved / Commitments
Провайдеры предлагают разные финансовые модели оплаты ресурсов:
Модели оплаты в облаке
| On-Demand / PAYG | Максимально дорого, гибко (посекундно) |
| Reserved / Savings | Скидка 30–60% за контракт на 1–3 года |
| Spot / Preemptible | Скидка 70–90% (могут забрать в любой момент) |
- Spot / Preemptible инстансы: Невостребованные мощности провайдера, которые продаются с огромной скидкой (до 80-90%), но могут быть отозваны с предупреждением за 30–120 секунд.
- Где применять: Воркеры очереди (Celery, RabbitMQ), узлы K8s для безсостояниевых (stateless) приложений, тестовые среды, CI/CD runners.
- Reserved Instances / Savings Plans / Committed Use: Если у вас есть базовая нагрузка (базы данных, production-сервера), которая точно проработает следующий год — оформляйте резервирование. Это даёт прямую скидку 30–50% без необходимости изменять архитектуру.
5. Борьба с Egress-трафиком (Исходящий трафик)
Исходящий трафик из облака в интернет или между регионами часто становится неожиданностью в конце месяца.
- Используйте VPC Endpoints / Internal Traffic: Трафик между вашим Compute-инстансом и S3 через публичный интернет тарифицируется. Использование внутренней маршрутизации (VPC Endpoints) снижает задержки и обнуляет/снижает затраты на трафик.
- CDN для статики: Раздача медиафайлов и статики напрямую из S3 стоит дорого. Подключение CDN (CloudFront, Cloudflare, Fastly) существенно снижает стоимость отдачи гигабайта пользователю.
- Сжатие: Включите gSOAP/gzip/brotli на уровне Nginx/Ingress, чтобы уменьшить объем передаваемых данных.
Чек-лист аудит-спринта для сисадмина
Для проведения первичного аудита выделите 2–3 дня и пройдитесь по следующему алгоритму:
- День 1: Чистка. Найти и удалить непривязанные EBS-диски, неиспользуемые IP, осиротевшие балансировщики и устаревшие снапшоты.
- День 2: Хранилище и Сеть. Настроить S3 Lifecycle Rules для логов и бэкапов. Проверить переходы на новые типы дисков (например, gp3).
- День 3: Размеры и Расписание. Сделать даунсайзинг недогруженных ВМ. Настроить автовыключение Dev/Stage на ночь.
- День 4: Финансы. Перевести stateless-нагрузки на Spot-инстансы, а постоянный Production зарезервировать (Savings Plan).
Итог
Аудит облачных расходов — это не одноразовая акция, а регулярный процесс (FinOps). Внедрение банальных правил гигиены, автоматизация удаления «мусора» и правильный выбор типов закупки ресурсов стабильно срезают 30–40% от ежемесячного счета, превращая сисадмина в глаза руководства из «центра затрат» в эффективного инженера.
 Share





