
The post has been translated automatically. Original language: Russian



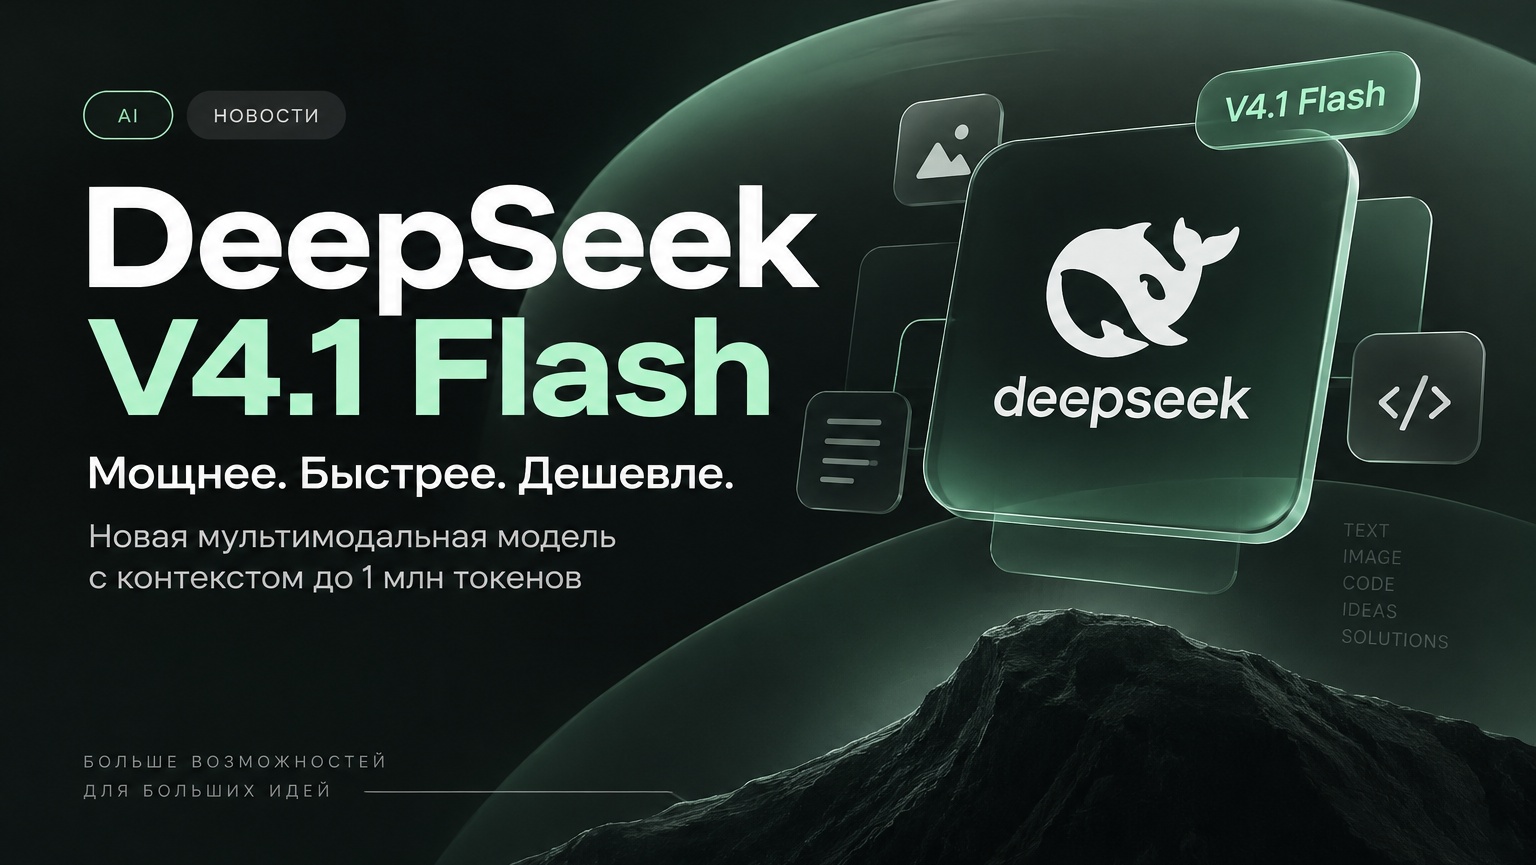
DeepSeek introduces V4.1 Flash: more powerful, faster and cheaper
On September 10, DeepSeek officially released the new V4.1 Flash model, the youngest model in the company's new architectural line.
The main change is to focus not only on increasing the capabilities of AI, but also on reducing the cost of using it.
DeepSeek V4.1 Flash has received native multimodality and can work with text and images. The model is built according to the architecture of Mixture-of-Experts and contains 552 billion parameters, however, only a small part of them is activated when processing the request.
The context window reaches 1 million tokens, which is especially interesting for AI agents working with large code bases, documents and corporate data.
Another important change is the optimization of the KV cache. According to DeepSeek, the new model requires significantly less memory, which reduces the cost of long-running agent scenarios and servicing a large number of requests.
The company claims that V4.1 Flash already surpasses the previous flagship V4 Pro in terms of performance, speed and cost. Therefore, after September 14, requests for V4 Pro are planned to be transferred to the new Flash model.
This is an important trend for startups: competition among AI models is gradually shifting away from the question "who is smarter?" to the question "who is able to provide comparable quality at a lower cost of computing?"
And it is the cost of inference that can become one of the key factors for the mass introduction of AI agents into products and businesses.
What do you think is more important for an AI startup now: maximizing the quality of the model or reducing the cost of a single query?
Source: DeepSeek, September 10, 2026.
🚀 DeepSeek представила V4.1 Flash: мощнее, быстрее и дешевле
10 сентября DeepSeek официально выпустила новую модель V4.1 Flash — младшую модель в новой архитектурной линейке компании.
Главное изменение — ставка не только на рост возможностей ИИ, но и на снижение стоимости его использования.
DeepSeek V4.1 Flash получила нативную мультимодальность и может работать с текстом и изображениями. Модель построена по архитектуре Mixture-of-Experts и содержит 552 млрд параметров, однако при обработке запроса активируется лишь небольшая их часть.
Контекстное окно достигает 1 млн токенов, что особенно интересно для AI-агентов, работы с большими кодовыми базами, документами и корпоративными данными.
Ещё одно важное изменение — оптимизация KV-cache. По данным DeepSeek, новой модели требуется значительно меньше памяти, что позволяет удешевить длительные агентные сценарии и обслуживание большого количества запросов.
Компания заявляет, что V4.1 Flash по производительности, скорости и стоимости уже превосходит предыдущую флагманскую V4 Pro. Поэтому после 14 сентября запросы к V4 Pro планируется переводить на новую Flash-модель.
Для стартапов это важный тренд: конкуренция среди AI-моделей постепенно смещается от вопроса «кто умнее?» к вопросу «кто способен дать сопоставимое качество при меньшей стоимости вычислений?»
И именно стоимость inference может стать одним из ключевых факторов массового внедрения AI-агентов в продукты и бизнес.
Как думаете, что сейчас важнее для AI-стартапа: максимальное качество модели или снижение стоимости одного запроса?
Источник: DeepSeek, 10 сентября 2026.
 Share