
The post has been translated automatically. Original language: English



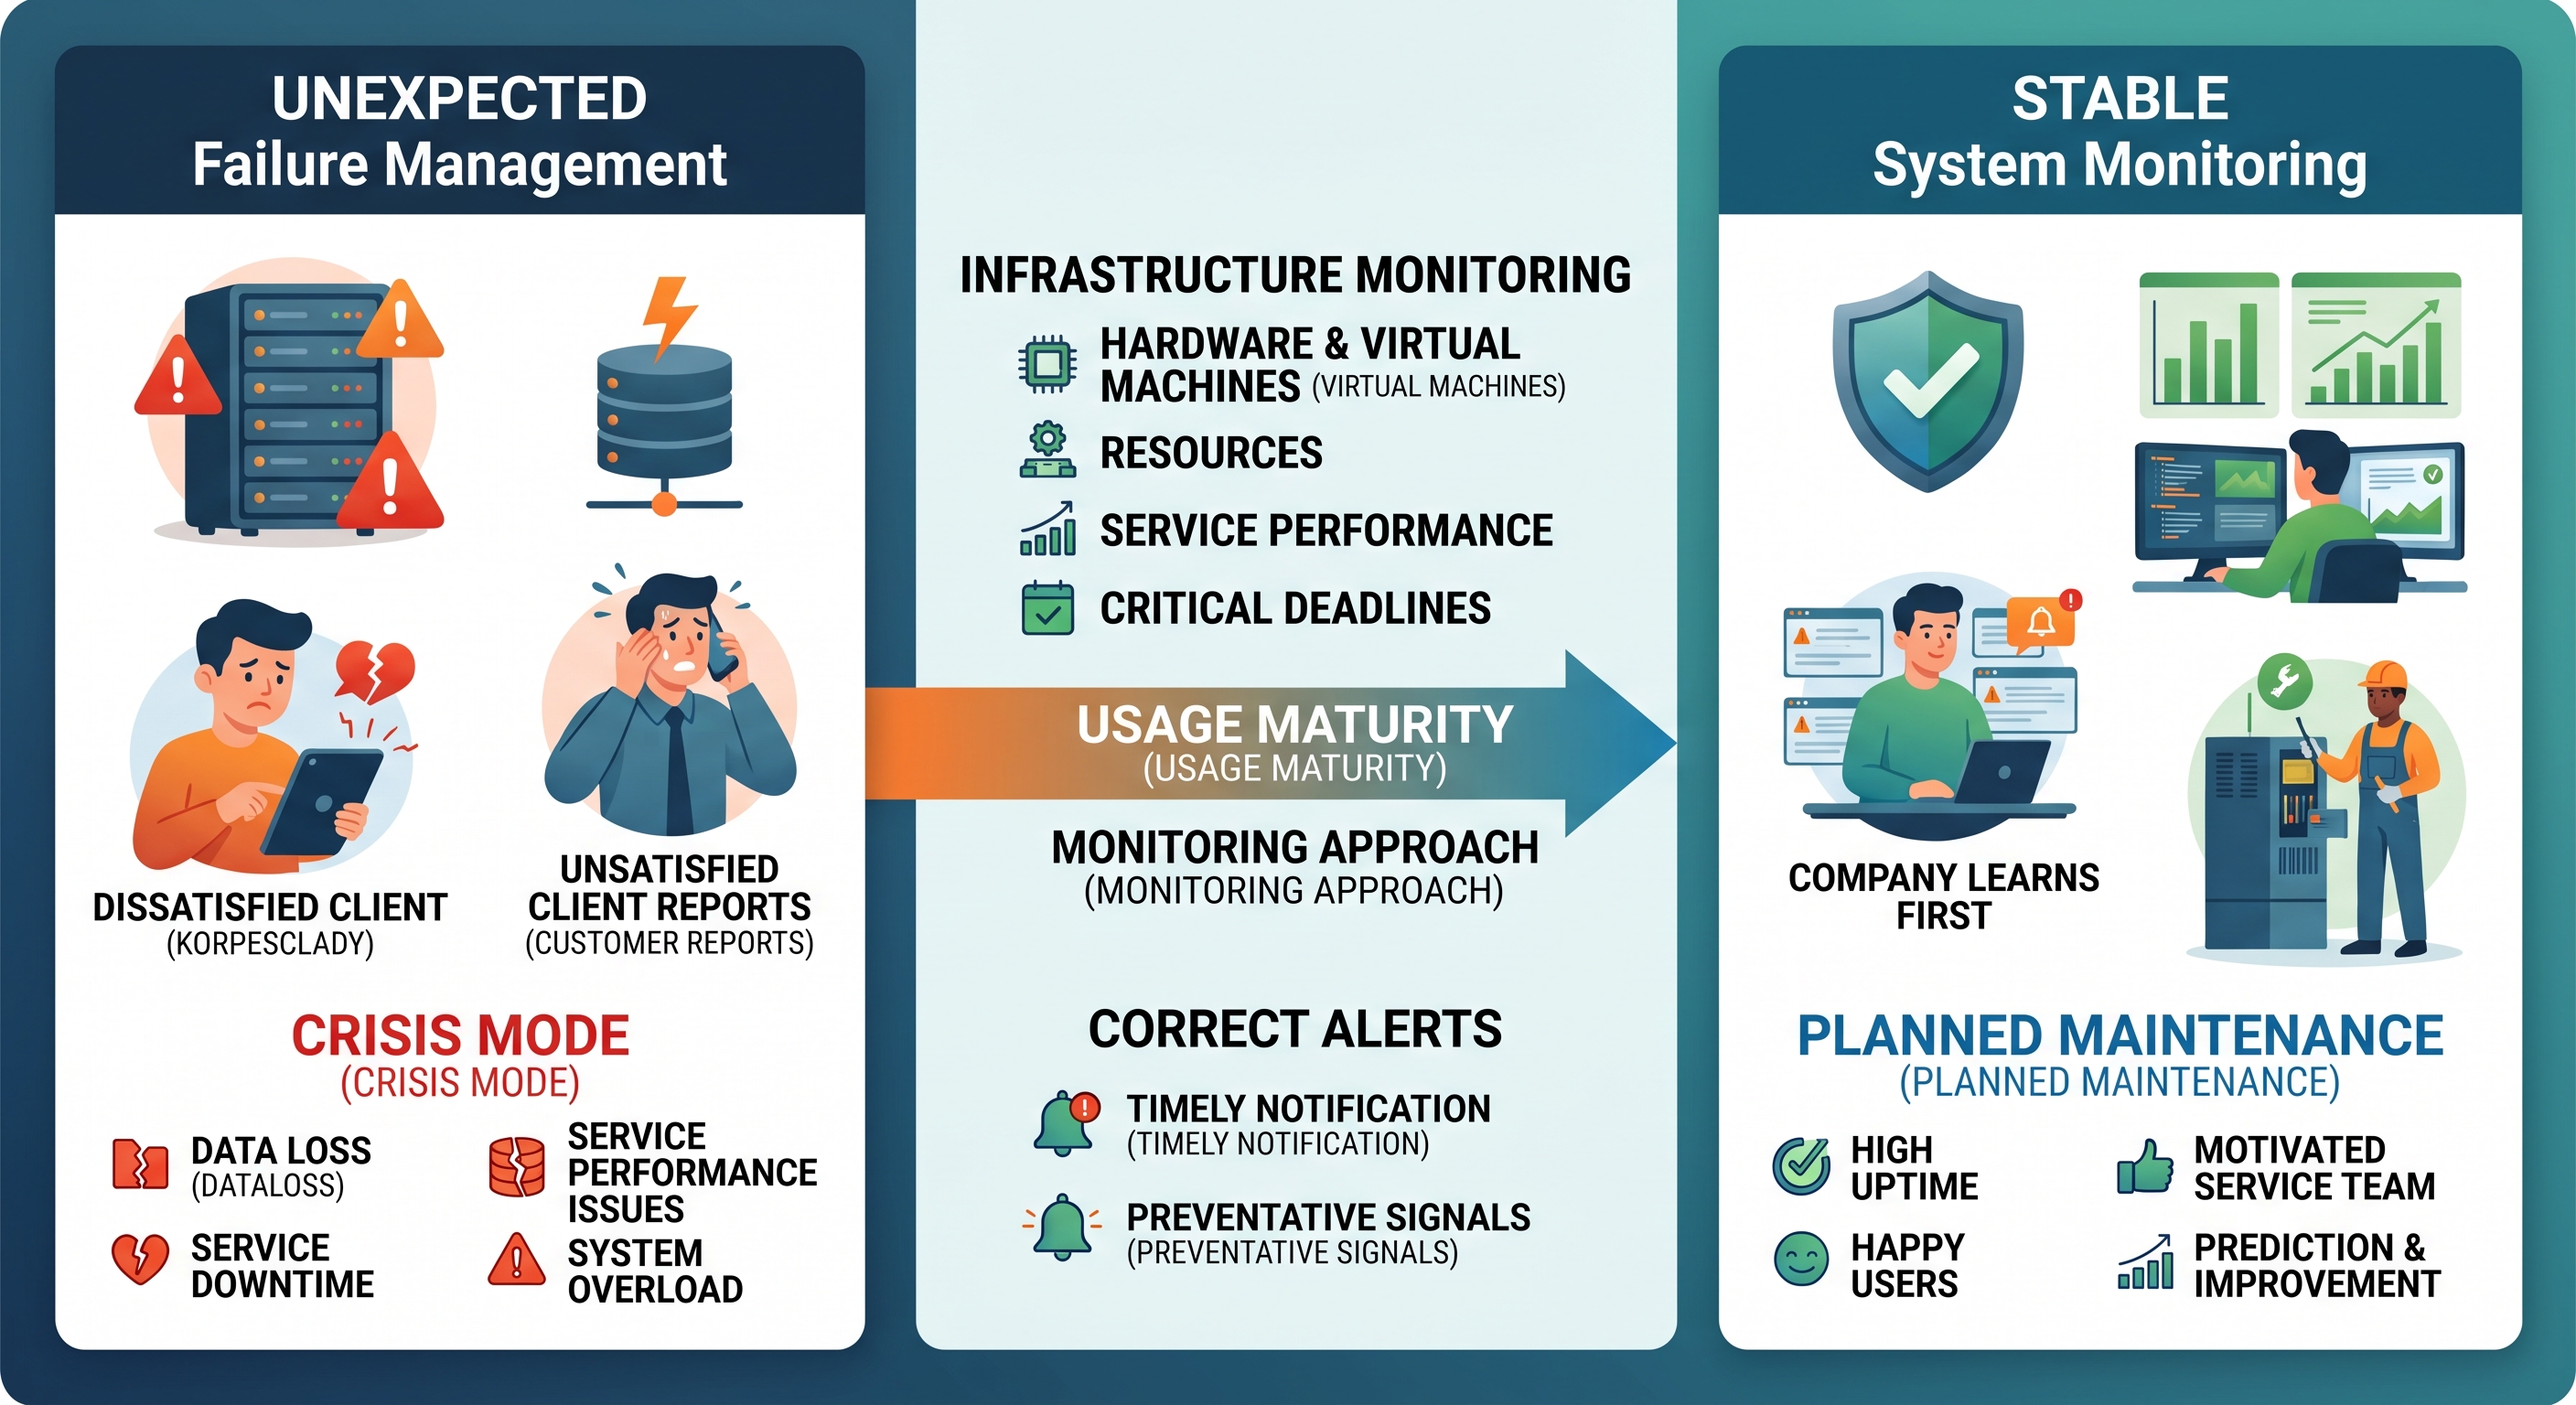
There are two ways to find out that the service is unavailable. The first is that a dissatisfied customer will report this. The second is that the company finds out about it on its own, even before anyone outside notices the problem. The distance between these scenarios determines the maturity of the operation, and ensures its monitoring.
Despite the obvious idea, a significant number of companies operate according to the first scenario. While the server is functioning, no one looks into its state — until the moment of failure. And when the failure occurs, it turns out that the disk space was gradually exhausted over the course of a week, the amount of free memory was reduced for months, and the certificate expired the day before. All these events could have been seen in advance.
What does infrastructure health monitoring mean?
Monitoring is not an employee monitoring charts, but an automated system that continuously checks key indicators and signals when values exceed acceptable limits. It makes sense to control several levels. Availability of the hardware itself and virtual machines. Resources — free disk space, memory capacity, and CPU usage. The efficiency of application services — the website, database, mail — and the speed of their response. Finally, critical deadlines are approaching, such as the expiration of an SSL certificate or domain registration.
The value is not in the charts, but in the alerts.
This is a common mistake. Companies implement a system with visual panels and graphs, and then they don't look into it. However, the point of monitoring is not the ability to monitor the condition, but the ability to notify those responsible in a timely manner when intervention is required. A well—configured notification — via messenger, email, or phone call - is much more important than visualization, which no one accesses. The system should report the problem itself, and then the company will be the first to know about it.
Higher level — warning before failure
Mature monitoring does not signal an accomplished failure, but an impending one. For example: with the current dynamics, the disk space will be exhausted within three days; the amount of occupied memory is steadily growing; the certificate expires in a week. This approach shifts the operation from the accident elimination mode to the scheduled maintenance mode, when the problem is solved during working hours, rather than in an emergency.
Where to start
You don't need to build a complex system right away. It is wise to start with one or two of the most critical services and set up a basic availability check with notification of the responsible person. There are plenty of suitable tools, including free and open source solutions ranging from simple accessibility verification tools to full—featured platforms. ""Even basic control moves the company from the category of "learning about failures from customers" to the category of "finding out first."
The reputation of a reliable service is based not on the absence of failures — they happen to everyone — but on the ability to detect a problem before the customer and fix it before it affects users.
 Share