

The post has been translated automatically. Original language: Russian



Imagine: a company has applied for financing through its personal account. All required fields are filled in, the documents are uploaded, the status has changed to "Accepted". But the specialist still has to open the applications, compare financial indicators, understand the structure of the project and draw up a conclusion.
Formally, the service has been transferred online. However, much of the substantive work in this scenario is still done manually.
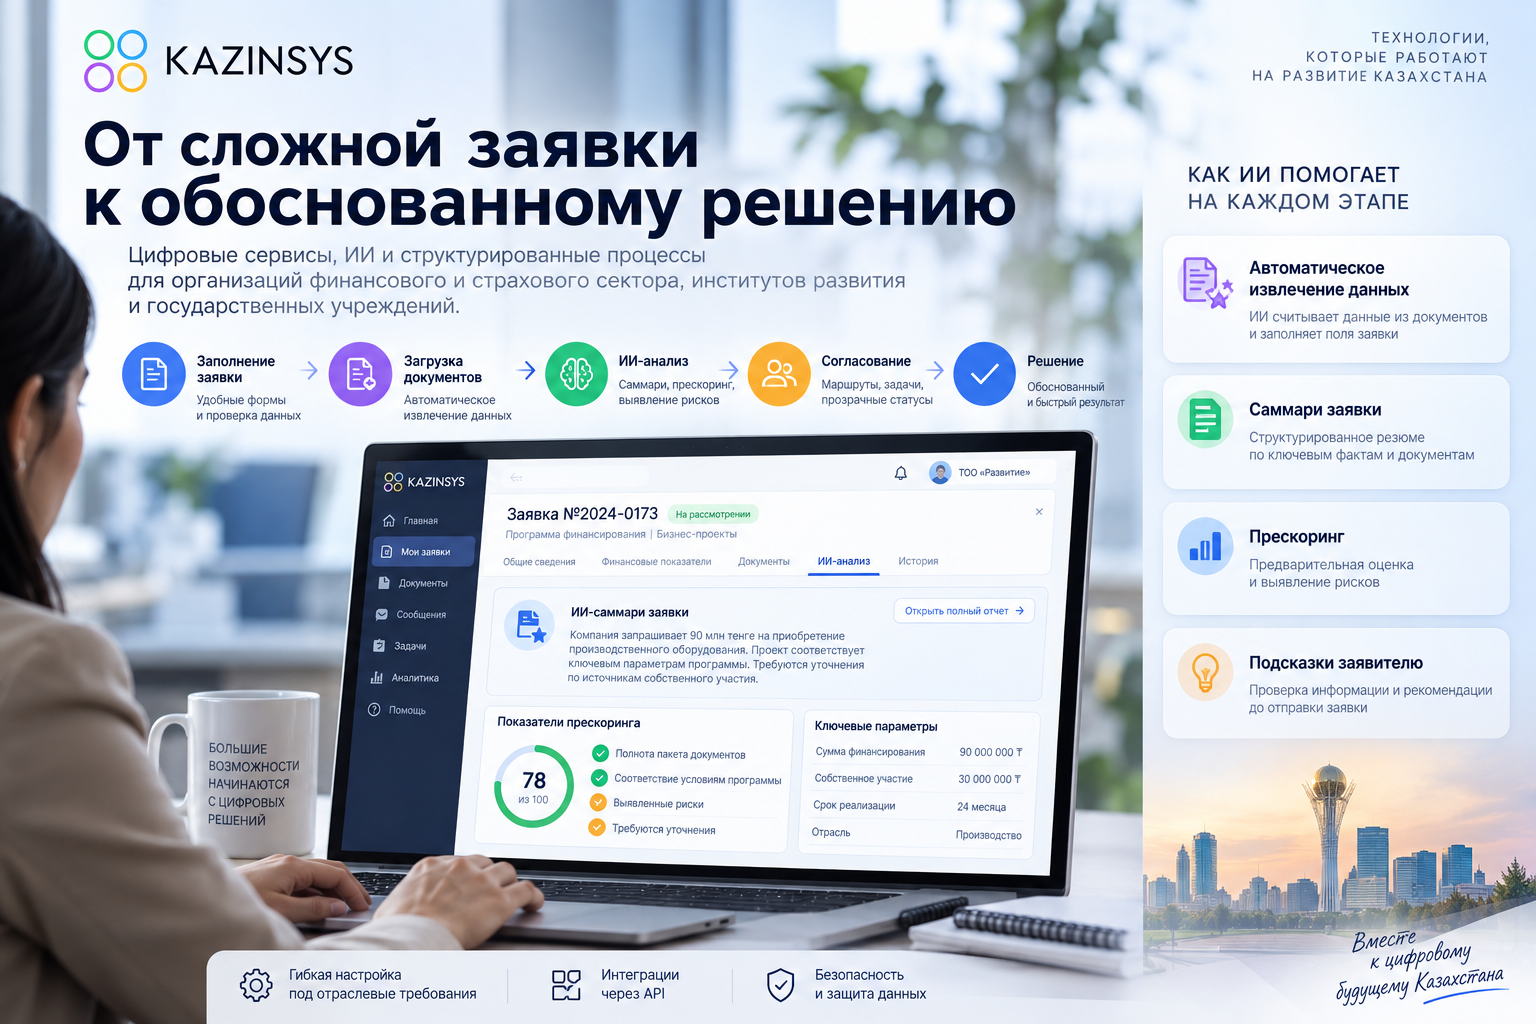
At KAZINSYS, we are developing personal accounts with complex electronic applications and are now using AI to prepare a sammari — a short structured resume — and prescoring, that is, a preliminary assessment of the application. In this article, we'll look at how to organize such processing, what industry nuances to consider, and what approaches can be adapted from international practice.
The main question here is not whether AI is capable of reading documents. It is important whether a specialist can verify on the basis of which the system has made each significant conclusion.
First — the structure of the application, then — artificial intelligence
When designing a complex application, it is useful to start with the question: why does the organization need each field?
For example, information about project participants can be used to verify ownership structure, financial indicators can be used to analyze business sustainability, and equipment descriptions can be used to assess the investment budget. If the purpose of the field is unclear, it is worth checking whether it is really necessary.
The visual designer simplifies the creation of a form, but does not replace this analytical work. Transferring a paper questionnaire to the screen without revising the structure risks preserving all the inconveniences of the original process.
For a large application, it makes sense to provide separate semantic blocks, saving the draft and an understandable status of each section. In our projects, a task list approach is used for multi-stage operations: the user sees what needs to be done, in what sequence and which parts have already been completed. For particularly large forms, it is also suggested to check the answers in individual sections, including when they are filled out by different participants.
In a corporate application, this can be applied as follows: the accountant fills out the financial section, the project manager fills in the technical part, and an authorized employee checks and sends the final package. Such a scenario requires separate access rights and commit changes, rather than transferring a single account between all participants.
A useful principle is to first make the data and responsibility for it clear, and only then connect AI to their processing.
Industry caveat: the same indicator names do not mean the same data.
Let's consider a conditional example. The questionnaire shows revenue of 120 million tenge, and in the attached statements — 120,000. A naive check will detect a discrepancy. However, if the financial statements are made in thousands of tenge, the values match.
Another example: one document shows the indicators of an individual legal entity, while the other shows the indicators of a group of companies. A simple comparison of the figures without accounting for the composition of the reports will give an incorrect result.
"""Therefore, for financial data, we suggest saving not only the value of the indicator, but also its context: period, currency, unit of measurement, organization, source, and the "fact" or "forecast" attribute.
This is also important when reviewing a business plan. Next year's planned revenue should not imperceptibly turn into a result already achieved. And the amount of the user's own participation is included in the confirmed availability of funds.
""""""""""""Different states are needed for the system here: "declared", "found in a document", "compared with another source", "confirmed by a specialist". "They should not be combined into one "data verified" label.
Sammari should help verify the application, not just shorten the text.
The request "briefly tell me the package of documents" is too broad a statement of the task for a working tool.
A pre-defined structure is more useful for a specialist: who applies, what is requested, how the financing is arranged, what information is confirmed and what questions remain open.
The following is a conditional example, not the data of a real client.
| The Sammari Block | Content |
| The essence of the appeal | The company requests 90 million tenge for the purchase of equipment. The "Financing" section of the application is the source. |
| Own participation | 30 million tenge has been declared. No supporting document was found in the submitted package. This does not mean that the company has no funds. |
| A question about the budget | The total cost of the project in the application is 120 million tenge, the cost of equipment in the contract is 115 million tenge. It is necessary to clarify the composition of the remaining expenses. |
| Next action | Request confirmation of your own participation and a budget statement. A final assessment of financial security has not yet been formed. |
This Sammari doesn't just save reading. It sets the verifiable order of further work.
For each essential statement, it is worth saving the transition to the application field, document page, or table row. At the same time, the link itself does not prove the correctness of the conclusion: a specialist should be able to check whether the source really confirms it.
A separate requirement is not to hide contradictions. If two documents contain different information, the system should show both values, rather than choosing the more convenient one on its own.
Prescoring: three checks instead of one opaque score
It is easy to turn prescoring into an effective, but little-explained function: the system gives out "82 out of 100", and users do not understand what exactly this rating means.
For design purposes, it is more useful to divide the preliminary analysis into three levels.
The first is the package's readiness for consideration. Have the necessary information been filled in, have the documents been attached, are the files readable, and is it possible to compare the data? It evaluates the quality of the application preparation, not the quality of the business itself.
The second is compliance with formal conditions. For example, whether the requested amount falls within the specified range and whether the project belongs to the specified area. It is better to check unambiguous conditions using separate programming rules. The language model can help extract information and explain the result, but it should not independently come up with restrictions.
The third is an analytical assessment. What circumstances require additional study? How well-founded are the assumptions of the business plan? Are there significant dependencies on individual suppliers or buyers? Here it is necessary to distinguish the discovered fact from the hypothesis, which has yet to be verified.
If a risk forecasting model is used, its result should be evaluated separately from the quality of the text sammari. The score generated by the language model cannot be automatically considered the probability of loan repayment or project success.
"""" For the workflow, we suggest providing at least three results of the preliminary check: "it is possible to proceed to the next stage," "clarifications are needed," and "non-compliance with a specific condition has been detected."
The lack of data is an independent result, not a hidden synonym for failure.
What can be learned from the international experience
International examples show two different areas of AI application: preparation of materials on the application and assistance in working with the rules for its consideration.
DBS: The AI is preparing a draft credit report. In August 2026, the bank announced the deployment of a corporate customer credit assessment solution for approximately 1,500 employees after a pilot with 150 participants. The system combines the initial information into the first draft of the loan agreement, which employees finalize taking into account industry expertise, customer knowledge and the context of the transaction. It is important to distinguish between the fact of implementation and the economic result: a reduction in time spent by at least 30% is indicated in the publication as a goal, and not as an already confirmed effect.
A practical conclusion for developers of personal accounts: a useful AI result may not be an automatic solution, but a dossier prepared for verification. Acceptance of an application and its meaningful evaluation are different stages, and they need to be automated in different ways.
Allianz: AI helps you find answers in the underwriting rules. In September 2025, Allianz UK described a working BRIAN tool. He answers the questions of insurance risk assessment specialists using the downloaded manuals. In other words, it helps not only to process the client's information, but also to find the rules by which this information should be evaluated.
For such a search, RAG can be used: the system finds suitable fragments of corporate documents and transmits them to the language model as the basis for the response. However, the quality of the result depends on the search and the content of the knowledge base; the presence of RAG does not eliminate the need to check the answers and manage access to documents.
From these cases, we draw a design conclusion: it is worth sharing information about the applicant and the evaluation rules. The business plan describes the project, but does not set the criteria for its approval.
Why Learning from Past Decisions Requires Caution
The idea seems obvious: take an archive of approved and rejected applications and teach the model to reproduce the decisions of specialists.
But first you need to determine what exactly needs to be predicted.
The historical "approved" means that the organization has made a positive decision. It does not in itself prove that the project was subsequently successful. A model trained on such labels will learn to reproduce past decisions, rather than necessarily predict future outcomes.
An additional problem arises in lending: the result of repayment of a specific loan is observed only where the loan was actually provided. There is no such monitoring for a rejected application. In machine learning research, this is seen as a problem of selectively observed outcomes — selective labels.
There is also a technical trap. The archive file may contain documents that appeared after the review: the final conclusion, information about the delay, or the project implementation report. If you use them to train a preliminary assessment, the model will receive information that is not available at the time of submission. Such a data leak can overestimate the quality of testing and lead to disappointment with new applications.
Therefore, for training and verification, it is necessary to restore the composition of information at the time when the assessment really should have been performed. Otherwise, the system actually answers the question, already knowing part of the future.
What else should be provided in your personal account?
The next area of development is assistance before submitting an application.
For example, the assistant may suggest filling in the fields with information from uploaded documents, showing possible discrepancies, and creating a list of missing materials. Such a scenario should be designed with user confirmation: the extracted value should not imperceptibly replace the one already entered.
It is useful to provide different explanations for the same result. The applicant needs a clear message: "Specify the period for which the revenue is indicated." For a specialist, it is technically detailed: what values are found, in which documents, and why they cannot be compared yet.
A separate issue is the version. If the user has replaced the business plan, the previous sammari cannot continue to be shown as an analysis of the current package. We suggest linking each AI result to specific versions of the application, documents, rules, and model. After changing the relevant data, the result should be recalculated or explicitly marked as outdated.
Finally, uploaded documents must be treated as an untrusted login. They may contain instructions aimed at changing the behavior of the AI, such as a requirement to ignore the verification rules. OWASP classifies such impacts through external materials as indirect prompt injection.
Therefore, the application text should not be authorized to change the evaluation criteria. AI access to data and actions should be limited at the application level, not just by a phrase in the system instructions. Rights verification, minimum permissions, and control of significant actions are separate elements of protection.
How to understand that implementation is really useful
We suggest evaluating such a tool not based on the quality of the demonstration, but based on the results of a comparison based on a pre-prepared set of applications.
For Sammari, it is necessary to check the correctness of the facts, the completeness of the essential circumstances and the correctness of references to sources. For pre—scoring, it is necessary to take into account missed issues and false comments separately. For the workflow, measure the total processing time, including checking and correcting the AI result.
The test set should include not only neatly executed applications, but also complex cases: an incomplete package, conflicting documents, different units of measurement, several versions of the business plan. For the Kazakh scenario, it is useful to check documents in Russian and Kazakh separately, as well as mixed packages.
We suggest starting with a mode in which the AI prepares the result in parallel with the usual review, but does not change the routing of the application and does not make a decision. This will allow you to collect discrepancies and understand where the system can really delegate some of the work.
When calculating the effect, it is important to take into account not only the cost of accessing the model. If a specialist has to search for the reasons for each conclusion for a long time or correct inconspicuous errors, the quickly generated text may not save money.
The main conclusion
In a complex electronic service, it is not enough to create a separate form, connect the approval separately, and add the "Analyze with AI" button separately.
It makes sense to build a single process.: The application collects structured data, the documents confirm the information, the AI prepares a verifiable resume, the rules provide reproducible checks, and the specialist makes an informed decision.
The most useful result of such automation is an unconvincingly written conclusion. This is a situation where participants understand what facts have been established, what is missing so far, and what action is really needed next.
Представим: компания подала заявку на финансирование через личный кабинет. Все обязательные поля заполнены, документы загружены, статус изменился на «Принято». Но специалисту ещё предстоит открыть приложения, сопоставить финансовые показатели, разобраться в структуре проекта и составить заключение.
Формально услуга переведена в онлайн. Однако значительная часть содержательной работы в этом сценарии по-прежнему выполняется вручную.
В KAZINSYS мы разрабатываем личные кабинеты со сложными электронными заявками и сейчас используем ИИ для подготовки саммари — краткого структурированного резюме — и прескоринга, то есть предварительной оценки заявки. В этой статье разберём, как организовать такую обработку, какие отраслевые нюансы предусмотреть и какие подходы можно перенести из международной практики.
Главный вопрос здесь не в том, способен ли ИИ прочитать документы. Важно, может ли специалист проверить, на основании чего система сделала каждый значимый вывод.
Сначала — структура заявки, потом — искусственный интеллект
При проектировании сложной заявки полезно начать с вопроса: зачем организации нужно каждое поле?
Например, сведения об участниках проекта могут использоваться для проверки структуры владения, финансовые показатели — для анализа устойчивости бизнеса, а описание оборудования — для оценки инвестиционного бюджета. Если назначение поля непонятно, стоит проверить, действительно ли оно необходимо.
Визуальный конструктор упрощает создание формы, но не заменяет эту аналитическую работу. Перенос бумажной анкеты на экран без пересмотра структуры рискует сохранить все неудобства исходного процесса.
Для большой заявки имеет смысл предусмотреть отдельные смысловые блоки, сохранение черновика и понятный статус каждого раздела. В наших проектах для многоэтапных операций используется подход со списком задач: пользователь видит, что необходимо сделать, в какой последовательности и какие части уже завершены. Для особенно больших форм также предлагается проверка ответов по отдельным разделам, в том числе когда их заполняют разные участники.
В корпоративной заявке это можно применить так: бухгалтер заполняет финансовый раздел, руководитель проекта — техническую часть, а уполномоченный сотрудник проверяет и отправляет итоговый пакет. Такой сценарий требует отдельных прав доступа и фиксации изменений, а не передачи одной учётной записи между всеми участниками.
Полезный принцип: сначала сделать понятными данные и ответственность за них, а уже затем подключать ИИ к их обработке.
Отраслевой нюанс: одинаковые названия показателей ещё не означают одинаковые данные
Рассмотрим условный пример. В анкете указана выручка 120 млн тенге, а в приложенной отчётности — 120 000. Наивная проверка обнаружит расхождение. Но если отчётность составлена в тысячах тенге, значения совпадают.
Другой пример: в одном документе приведены показатели отдельного юридического лица, а в другом — группы компаний. Простое сравнение цифр без учёта состава отчётности даст неверный результат.
Поэтому для финансовых данных предлагаем сохранять не только значение показателя, но и его контекст: период, валюту, единицу измерения, организацию, источник и признак «факт» или «прогноз».
Это важно и при проверке бизнес-плана. Плановая выручка следующего года не должна незаметно превращаться в саммари в уже достигнутый результат. А сумма собственного участия, заявленная пользователем, — в подтверждённое наличие средств.
Для системы здесь нужны разные состояния: «заявлено», «найдено в документе», «сопоставлено с другим источником», «подтверждено специалистом». Их не стоит объединять в одну отметку «данные проверены».
Саммари должно помогать проверять заявку, а не только сокращать текст
Просьба «кратко перескажи пакет документов» — слишком широкая постановка задачи для рабочего инструмента.
Для специалиста полезнее заранее определённая структура: кто обращается, что запрашивает, как устроено финансирование, какие сведения подтверждены и какие вопросы остаются открытыми.
Ниже — условный пример, а не данные реального клиента.
| Блок саммари | Содержание |
| Суть обращения | Компания запрашивает 90 млн тенге на приобретение оборудования. Источник — раздел заявки «Финансирование». |
| Собственное участие | Заявлено 30 млн тенге. В представленном пакете подтверждающий документ не найден. Это не означает, что средств у компании нет. |
| Вопрос к бюджету | Общая стоимость проекта в заявке — 120 млн тенге, стоимость оборудования в договоре — 115 млн тенге. Необходимо уточнить состав остальных расходов. |
| Следующее действие | Запросить подтверждение собственного участия и расшифровку бюджета. Окончательную оценку финансовой обеспеченности пока не формировать. |
Такое саммари не просто экономит чтение. Оно задаёт проверяемый порядок дальнейшей работы.
Для каждого существенного утверждения стоит сохранять переход к полю заявки, странице документа или строке таблицы. При этом сама ссылка ещё не доказывает правильность вывода: специалист должен иметь возможность проверить, действительно ли источник его подтверждает.
Отдельное требование — не скрывать противоречия. Если два документа содержат разные сведения, система должна показать оба значения, а не самостоятельно выбрать более удобное.
Прескоринг: три проверки вместо одного непрозрачного балла
Прескоринг легко превратить в эффектную, но малообъяснимую функцию: система выдаёт «82 из 100», а пользователи не понимают, что именно означает эта оценка.
Для проектирования полезнее разделить предварительный анализ на три уровня.
Первый — готовность пакета к рассмотрению. Заполнены ли необходимые сведения, приложены ли документы, читаются ли файлы, можно ли сопоставить данные? Здесь оценивается качество подготовки заявки, а не качество самого бизнеса.
Второй — соответствие формальным условиям. Например, укладывается ли запрашиваемая сумма в установленный диапазон и относится ли проект к предусмотренному направлению. Однозначные условия лучше проверять отдельными программными правилами. Языковая модель может помогать извлекать сведения и объяснять результат, но не должна самостоятельно придумывать ограничения.
Третий — аналитическая оценка. Какие обстоятельства требуют дополнительного изучения? Насколько обоснованы предположения бизнес-плана? Есть ли существенные зависимости от отдельных поставщиков или покупателей? Здесь необходимо отличать обнаруженный факт от гипотезы, которую ещё предстоит проверить.
Если применяется модель прогнозирования риска, её результат нужно оценивать отдельно от качества текстового саммари. Балл, сгенерированный языковой моделью, нельзя автоматически считать вероятностью возврата кредита или успешности проекта.
Для рабочего процесса предлагаем предусматривать как минимум три результата предварительной проверки: «можно переходить к следующему этапу», «необходимы уточнения» и «обнаружено несоответствие конкретному условию».
Отсутствие данных — самостоятельный результат, а не скрытый синоним отказа.
Что можно взять из международного опыта
Международные примеры показывают два разных направления применения ИИ: подготовку материалов по заявке и помощь в работе с правилами её рассмотрения.
DBS: ИИ готовит проект кредитного заключения. В августе 2026 года банк сообщил о развёртывании решения для подготовки кредитных оценок корпоративных клиентов примерно для 1 500 сотрудников после пилота со 150 участниками. Система объединяет исходные сведения в первый проект кредитного заключения, который сотрудники дорабатывают с учётом отраслевой экспертизы, знания клиента и контекста сделки. Важно различать факт внедрения и экономический результат: сокращение затрат времени не менее чем на 30% в публикации обозначено как цель, а не как уже подтверждённый эффект.
Практический вывод для разработчиков личных кабинетов: полезным результатом ИИ может быть не автоматическое решение, а подготовленное к проверке досье. Приём заявки и её содержательная оценка — разные этапы, и автоматизировать их нужно по-разному.
Allianz: ИИ помогает искать ответы в правилах андеррайтинга. В сентябре 2025 года Allianz UK описала работающий инструмент BRIAN. Он отвечает на вопросы специалистов по оценке страховых рисков, используя загруженные руководства. То есть помогает не только обрабатывать сведения клиента, но и находить правила, по которым эти сведения следует оценивать.
Для подобного поиска может применяться RAG: система находит подходящие фрагменты корпоративных документов и передаёт их языковой модели как основу ответа. Однако качество результата зависит от поиска и содержания базы знаний; наличие RAG не отменяет необходимости проверять ответы и управлять доступом к документам.
Из этих кейсов мы делаем проектный вывод: стоит разделять информацию о заявителе и правила оценки. Бизнес-план описывает проект, но не устанавливает критерии его одобрения.
Почему обучение на прошлых решениях требует осторожности
Идея кажется очевидной: взять архив одобренных и отклонённых заявок и научить модель воспроизводить решения специалистов.
Но сначала необходимо определить, что именно требуется прогнозировать.
Историческое «одобрено» означает, что организация приняла положительное решение. Оно само по себе не доказывает, что проект впоследствии оказался успешным. Модель, обученная на таких метках, будет учиться воспроизводить прошлые решения, а не обязательно прогнозировать будущий результат.
В кредитовании возникает дополнительная проблема: результат погашения конкретного кредита наблюдается только там, где кредит действительно был предоставлен. Для отклонённой заявки такого наблюдения нет. В исследованиях машинного обучения это рассматривается как проблема избирательно наблюдаемых результатов — selective labels.
Есть и техническая ловушка. В архивном досье могут находиться документы, которые появились после рассмотрения: итоговое заключение, сведения о просрочке или отчёт о реализации проекта. Если использовать их при обучении предварительной оценки, модель получит информацию, недоступную на момент подачи. Такая утечка данных способна завысить качество тестирования и привести к разочарованию на новых заявках.
Поэтому для обучения и проверки необходимо восстанавливать состав информации на момент, когда оценка действительно должна была выполняться. Иначе система фактически отвечает на вопрос, уже зная часть будущего.
Что ещё стоит предусмотреть в личном кабинете
Следующее направление развития — помощь до отправки заявки.
Например, ассистент может предложить заполнить поля сведениями из загруженных документов, показать возможные расхождения и сформировать список недостающих материалов. Такой сценарий стоит проектировать с подтверждением пользователя: извлечённое значение не должно незаметно заменять уже введённое.
Полезно предусмотреть и разные объяснения одного результата. Заявителю нужно понятное сообщение: «Уточните период, за который указана выручка». Специалисту — технически подробное: какие значения найдены, в каких документах и почему их пока нельзя сопоставить.
Отдельный вопрос — версии. Если пользователь заменил бизнес-план, прежнее саммари нельзя продолжать показывать как анализ актуального пакета. Предлагаем связывать каждый результат ИИ с конкретными версиями заявки, документов, правил и модели. После изменения значимых данных результат следует пересчитать либо явно обозначить как устаревший.
Наконец, загруженные документы необходимо рассматривать как недоверенный вход. В них могут находиться инструкции, направленные на изменение поведения ИИ, — например, требование игнорировать правила проверки. OWASP относит такие воздействия через внешние материалы к непрямым prompt injection.
Поэтому текст заявки не должен получать полномочия менять критерии оценки. Доступ ИИ к данным и действиям стоит ограничивать на уровне приложения, а не только фразой в системной инструкции. Проверка прав, минимальные разрешения и контроль значимых действий — отдельные элементы защиты.
Как понять, что внедрение действительно полезно
Мы предлагаем оценивать такой инструмент не по качеству демонстрации, а по результатам сравнения на заранее подготовленном наборе заявок.
Для саммари следует проверять правильность фактов, полноту существенных обстоятельств и корректность ссылок на источники. Для прескоринга — отдельно учитывать пропущенные проблемы и ложные замечания. Для рабочего процесса — измерять полное время обработки, включая проверку и исправление результата ИИ.
В тестовый набор стоит включать не только аккуратно оформленные заявки, но и сложные случаи: неполный пакет, противоречащие документы, разные единицы измерения, несколько версий бизнес-плана. Для казахстанского сценария полезно отдельно проверять документы на русском и казахском языках, а также смешанные пакеты.
Начинать предлагаем с режима, в котором ИИ готовит результат параллельно обычному рассмотрению, но не меняет маршрутизацию заявки и не принимает решение. Это позволит собрать расхождения и понять, где системе действительно можно делегировать часть работы.
При расчёте эффекта важно учитывать не только стоимость обращения к модели. Если специалисту приходится долго искать основания каждого вывода или исправлять незаметные ошибки, быстро сгенерированный текст может не давать экономии.
Главный вывод
В сложной электронной услуге недостаточно отдельно создать форму, отдельно подключить согласование и отдельно добавить кнопку «Проанализировать с ИИ».
Имеет смысл выстраивать единый процесс: заявка собирает структурированные данные, документы подтверждают сведения, ИИ готовит проверяемое резюме, правила обеспечивают воспроизводимые проверки, а специалист принимает обоснованное решение.
Самый полезный результат такой автоматизации — не убедительно написанное заключение. Это ситуация, когда участникам понятно, какие факты установлены, чего пока не хватает и какое действие действительно необходимо дальше.
 Share





