



The post has been translated automatically. Original language: Russian




Programmers are used to thinking first of all about the code. The code performs the work, contains algorithms, accesses the database, makes decisions and creates the result. Therefore, it is easy to decide that it is the program that is the main part of the system, and the data is only the material that it processes.
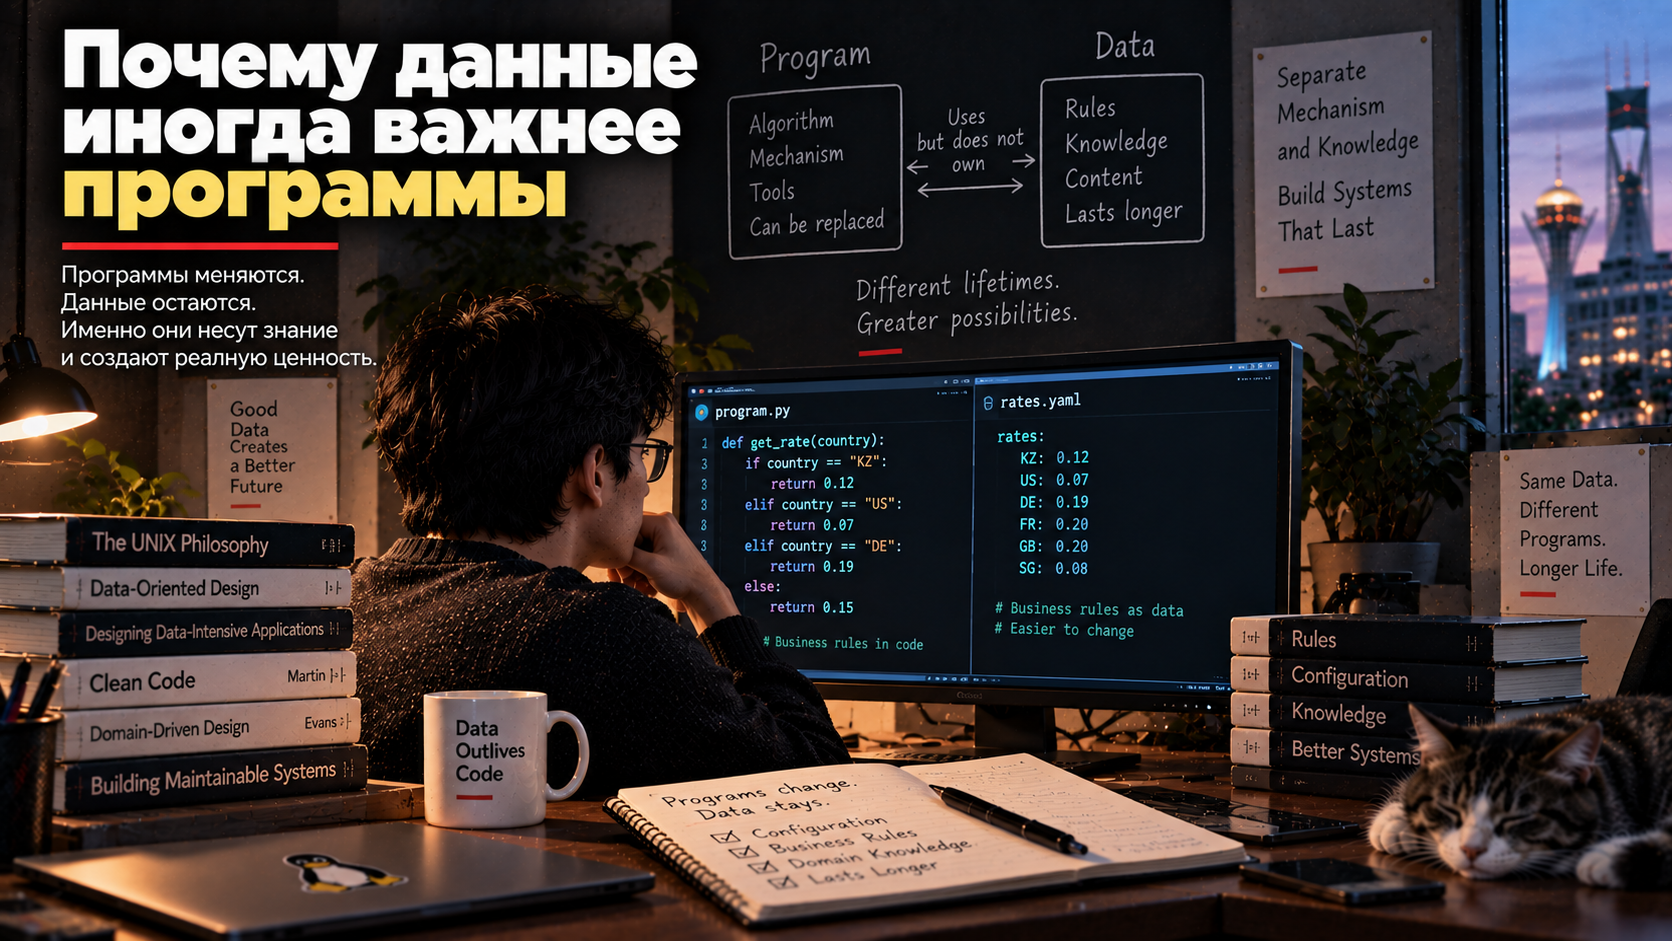
There is a different view in Unix culture. If some part of the behavior can be expressed through data, description, or rules, it is often better not to hide it inside the program. The code is responsible for the mechanism, and the knowledge of what exactly needs to be done can exist separately.
This idea has survived the times especially well. Today, programs are changing faster than accumulated data, rules, and knowledge.
Code and data live in different ways
Let's imagine a program in which the list of supported devices is written directly in the source code. To add a new device, you need to change the program, build a new version and install it.
You can do it differently. The program can read device descriptions from a separate file. Then it is not necessary to change the mechanism itself to add a new option.
In both cases, the result may be the same. But the architecture turns out to be completely different.
In the first case, knowledge belongs to the program. In the second case, it exists separately, and the program only knows how to apply it.
And the more the system evolves, the more significant this difference becomes.
Not everything has to be an algorithm
It is natural for a programmer to express the solution of a problem in code. A new rule has been added — a condition has been added. There was an exception — another condition. We need to support the new version — we added another branch.
This way, not only algorithms, but also knowledge about the subject area gradually accumulates inside the program.
What types of documents exist. What values are acceptable. Which countries are supported. Which tariff to use in a certain situation. How to handle a specific exception. Which actions are allowed in one state and prohibited in another.
Technically, all this can be expressed in code. The question is, is it worth it?
If the rule is data in nature, it is useful to leave it as data.
A table is sometimes better than hundreds of conditions
A good example is the correspondence of some values to others.
You can write a long sequence of conditions: if the value A has arrived, use B; if C, use D; if E— use E. The code will work.
But you can store matches in a table, and teach the program to read this table.
In the second case, the mechanism becomes simpler. He no longer knows all the possible meanings. He knows only one rule: find the right record and apply it.
New data is being added, but the code itself may not change at all.
This is an important architectural transition: the program ceases to contain specific knowledge and begins to contain a way to apply it.
The data is easier to see
There is another advantage. The rule hidden inside the program is difficult for a person who does not write code to see.
If dozens of conditions are scattered across several functions, you will have to read the program and mentally assemble the picture to understand the real behavior of the system.
If the same rules are represented by a table, a list, or a separate description, they become visible.
You can open the file and see all the options at once. You can compare the two versions. You can find the missing value. You can discuss the rule with someone who is not a programmer at all.
The system becomes not only simpler technically, but also clearer organizationally.
Data is easier to change
Changing the code usually requires some process.: make an edit, check it, build the program, release a new version.
Changing data can often be done much easier.
Of course, this does not mean that the data can be changed without verification. An erroneous configuration can break the system no worse than an erroneous code. But the types of changes themselves are becoming separated.
The developer is changing the mechanism. The person in charge of the subject area changes the rules and content.
When this boundary is drawn correctly, the system becomes more flexible.
The program may disappear, but the data will remain
Programs have a relatively short life.
Languages change. New libraries are being added. The old server is being replaced with a new one. The system is being rewritten. The company is switching from one software product to another.
Data often lives much longer.
The list of clients, the history of operations, technical parameters, accumulated solutions, documents, operating rules — all this can exist for decades and survive several generations of programs.
Therefore, an architecture in which data is too tightly coupled to a specific application creates a long-term problem.
The program will have to be replaced one day. And then it will become clear how easily knowledge and information can live without it.
The data format becomes part of the architecture
If the data is to survive the program, it is important not only to take it outside, but also to present it in a fairly understandable format.
A closed internal structure is also formally data. But if only one specific version of one specific program can read it, the independence is imaginary.
A good format has a clear structure and a clear meaning. Preferably, it can be tested, converted, and used with other tools.
This is why Unix so often relied on simple text formats. They were not the most economical way to store information, but they separated the data from the program well.
Configuration is also a program, only of a different kind.
There is an interesting boundary here. The richer the data description becomes, the more it begins to resemble a programming language.
The list of values appears first. Then the terms. Then the variables. Then the calculations. After a while, the configuration file turns into almost a full-fledged program.
This is not always a bad thing, but it's easy to lose the original simplicity here.
If you need to learn a separate complex language to understand the settings, some of the advantages disappear. Instead of hidden logic in the source code, we get hidden logic in the configuration.
Therefore, it is useful to keep a distinction: the mechanism can be complex, and the data it controls should remain understandable if possible.
The database does not solve this problem automatically.
You might think that the issue has already been resolved today: we simply store everything important in the database.
But the database itself does not guarantee anything.
If the meaning of the information is determined only by the program code, the data still remains application-dependent. The number 7 may be in the table, but without the program, no one knows whether it means the status of the order, the type of customer, or the payment method.
Good data should have not only a storage location, but also a clear meaning.
Structure, names, relationships, constraints, and documentation are all part of the data no less than the values themselves.
Knowledge is a special kind of data
This idea is especially interesting when it comes not just to numbers and strings, but to knowledge.
In many programs, professional rules have been accumulating directly in the code for years. The developer receives another requirement and adds a new condition. Then an exception appears. Then the exception of the exception.
After a few years, the program actually contains a huge amount of organizational experience, but this experience cannot be seen separately from the code.
If you try to answer the question of what rules the system uses to make a decision, you have to analyze the program.
This is a sign that the data and the mechanism are too much mixed up.
Artificial intelligence has increased the problem
Before the advent of modern language models, hidden knowledge was mostly in software code or in people's heads.
Now there is another option: knowledge can end up inside long instructions, conversation history, or the model itself.
It's convenient. You can explain the rule to the system in ordinary language and immediately get the result.
But a familiar problem arises. Where is the rule located now? Who formulated it? When did it change? Does it always work or only in certain situations? How can I tell which version the system was using?
If all this exists only inside a conversation with artificial intelligence, knowledge is again associated with a specific tool.
The form of the problem is changing, but the problem itself is old.
The code needs to know how to apply the rule, not the rule itself is mandatory
A useful architectural boundary looks something like this.
There is a mechanism that can do some work. There is data or knowledge that determines a particular behavior. There is a clear way for them to interact.
Then you can change the mechanism without losing knowledge.
You can replace the program with another one. You can use another language. You can connect artificial intelligence. You can change the storage method.
As long as the knowledge itself exists separately and has an understandable form, it remains the property of the system or person, and not of a specific application.
But not everything needs to be taken out.
Like many Unix principles, it's easy to turn this idea into a dogma.
There is no need to try to represent the entire code with data at all. Algorithms remain algorithms. Integrity checking, memory management, network data transmission, error handling, and many other tasks are naturally expressed by the program.
The question should be asked where mutable knowledge appears.
Is it an algorithm or a rule? A mechanism or a specific meaning? A universal behavior or a decision that may change tomorrow?
If the content is changing, rather than the mechanism itself, we may be looking at data.
A good system outlives its own code
There is an interesting way to test the architecture.
Let's imagine that after five years, the current program no longer exists. It was rewritten in a different language, replaced with another product, or even divided into several new systems.
What's left?
If the settings, rules, structure, accumulated decisions, and meaning of the data disappear along with the program, then too much belonged to the code.
If the new application can take the same data and continue working, the boundary has been drawn better.
That's why data is sometimes more important than a program.
Programs come and go. The mechanisms are changing. Tools are becoming fashionable and outdated.
And the accumulated information, rules, and knowledge can be valuable much longer than any particular code.
Программисты привыкли думать прежде всего о коде. Код выполняет работу, содержит алгоритмы, обращается к базе, принимает решения и создаёт результат. Поэтому легко решить, что именно программа является главной частью системы, а данные — лишь материалом, который она обрабатывает.
В Unix-культуре есть другой взгляд. Если какую-то часть поведения можно выразить через данные, описание или правила, часто лучше не прятать её внутрь программы. Код отвечает за механизм, а знания о том, что именно нужно делать, могут существовать отдельно.
Эта идея особенно хорошо пережила время. Сегодня программы меняются быстрее, чем накопленные данные, правила и знания.
Код и данные живут по-разному
Представим программу, в которой список поддерживаемых устройств записан прямо в исходном коде. Чтобы добавить новое устройство, нужно изменить программу, собрать новую версию и установить её.
Можно сделать иначе. Программа умеет читать описание устройств из отдельного файла. Тогда для добавления нового варианта не обязательно менять сам механизм.
В обоих случаях результат может быть одинаковым. Но архитектура получается совершенно разной.
В первом случае знание принадлежит программе. Во втором оно существует отдельно, а программа лишь умеет его применять.
И чем больше система развивается, тем существеннее становится эта разница.
Не всё должно быть алгоритмом
Программисту естественно выражать решение задачи кодом. Появилось новое правило — добавили условие. Появилось исключение — ещё одно условие. Нужно поддержать новый вариант — добавили ещё одну ветку.
Так постепенно внутри программы накапливаются не только алгоритмы, но и знания о предметной области.
Какие типы документов существуют. Какие значения допустимы. Какие страны поддерживаются. Какой тариф использовать в определённой ситуации. Как обработать конкретное исключение. Какие действия разрешены в одном состоянии и запрещены в другом.
Технически всё это можно выразить кодом. Вопрос в том, стоит ли это делать.
Если правило является данными по своей природе, полезно оставить его данными.
Таблица иногда лучше сотни условий
Хороший пример — соответствие одних значений другим.
Можно написать длинную последовательность условий: если пришло значение А, использовать Б; если В — использовать Г; если Д — использовать Е. Код будет работать.
Но можно хранить соответствия в таблице, а программу научить читать эту таблицу.
Во втором случае механизм становится проще. Он больше не знает все возможные значения. Он знает только одно правило: найти нужную запись и применить её.
Добавляются новые данные, но сам код при этом может вообще не измениться.
Это и есть важный архитектурный переход: программа перестаёт содержать конкретные знания и начинает содержать способ их применения.
Данные легче увидеть
Есть ещё одно преимущество. Правило, спрятанное внутри программы, трудно увидеть человеку, который не пишет код.
Если десятки условий разбросаны по нескольким функциям, для понимания реального поведения системы придётся читать программу и мысленно собирать картину.
Если те же правила представлены таблицей, списком или отдельным описанием, они становятся видимыми.
Можно открыть файл и увидеть все варианты сразу. Можно сравнить две версии. Можно найти пропущенное значение. Можно обсудить правило с человеком, который вообще не является программистом.
Система становится не только проще технически, но и понятнее организационно.
Данные легче менять
Изменение кода обычно требует некоторого процесса: внести правку, проверить её, собрать программу, выпустить новую версию.
Изменение данных часто можно выполнить значительно проще.
Конечно, это не означает, что данные можно менять без проверки. Ошибочная конфигурация способна сломать систему не хуже ошибочного кода. Но сами типы изменений становятся разделены.
Разработчик меняет механизм. Человек, отвечающий за предметную область, меняет правила и содержание.
Когда эта граница проведена правильно, система становится гибче.
Программа может исчезнуть, данные останутся
У программ относительно короткая жизнь.
Меняются языки. Появляются новые библиотеки. Старый сервер заменяется новым. Система переписывается. Компания переходит с одного программного продукта на другой.
Данные часто живут намного дольше.
Список клиентов, история операций, технические параметры, накопленные решения, документы, правила работы — всё это может существовать десятилетиями и пережить несколько поколений программ.
Поэтому архитектура, в которой данные слишком тесно связаны с конкретным приложением, создаёт долговременную проблему.
Программу однажды придётся заменить. И тогда выяснится, насколько легко знания и информация могут жить без неё.
Формат данных становится частью архитектуры
Если данные должны пережить программу, важно не только вынести их наружу, но и представить в достаточно понятном формате.
Закрытая внутренняя структура формально тоже является данными. Но если прочитать её может только одна конкретная версия одной конкретной программы, независимость получается мнимой.
Хороший формат имеет понятную структуру и чёткий смысл. Желательно, чтобы его можно было проверить, преобразовать и использовать другими инструментами.
Именно поэтому Unix так часто опирался на простые текстовые форматы. Они были не самым экономным способом хранения информации, зато хорошо отделяли данные от программы.
Конфигурация — тоже программа, только другого вида
Здесь есть интересная граница. Чем богаче становится описание данных, тем сильнее оно начинает напоминать язык программирования.
Сначала появляется список значений. Потом условия. Затем переменные. Потом вычисления. Через некоторое время конфигурационный файл превращается почти в полноценную программу.
Это не всегда плохо, но здесь легко потерять исходную простоту.
Если для понимания настроек нужно изучить отдельный сложный язык, часть преимуществ исчезает. Вместо скрытой логики в исходном коде мы получаем скрытую логику в конфигурации.
Поэтому полезно сохранять различие: механизм может быть сложным, а данные, которыми он управляется, по возможности должны оставаться понятными.
База данных не решает эту проблему автоматически
Можно подумать, что сегодня вопрос уже решён: всё важное мы просто храним в базе данных.
Но сама по себе база ничего не гарантирует.
Если смысл информации определяется только программным кодом, данные всё ещё остаются зависимыми от приложения. В таблице может лежать число 7, но без программы никто уже не знает, означает оно состояние заказа, тип клиента или способ оплаты.
Хорошие данные должны иметь не только место хранения, но и понятный смысл.
Структура, названия, связи, ограничения и документация — всё это часть данных не меньше, чем сами значения.
Знание — особый вид данных
Особенно интересно эта идея выглядит, когда речь идёт не просто о числах и строках, а о знаниях.
Во многих программах профессиональные правила годами накапливаются непосредственно в коде. Разработчик получает очередное требование и добавляет новое условие. Потом появляется исключение. Затем исключение из исключения.
Через несколько лет программа фактически содержит огромный объём опыта организации, но этот опыт нельзя увидеть отдельно от кода.
Если попытаться ответить на вопрос, по каким правилам система принимает решение, приходится анализировать программу.
Это признак того, что данные и механизм слишком сильно смешались.
Искусственный интеллект усилил проблему
До появления современных языковых моделей скрытое знание находилось в основном в программном коде или в головах людей.
Теперь появился ещё один вариант: знание может оказаться внутри длинных инструкций, истории разговоров или самой модели.
Это удобно. Можно объяснить системе правило обычным языком и сразу получить результат.
Но возникает знакомая проблема. Где теперь находится правило? Кто его сформулировал? Когда оно изменилось? Действует ли оно всегда или только в определённых ситуациях? Как понять, какую версию использовала система?
Если всё это существует только внутри разговора с искусственным интеллектом, знание снова оказывается связано с конкретным инструментом.
Меняется форма проблемы, но сама проблема старая.
Код должен знать, как применять правило, а не обязательно само правило
Полезная архитектурная граница выглядит примерно так.
Есть механизм, который умеет выполнить некоторую работу. Есть данные или знания, определяющие конкретное поведение. Между ними существует понятный способ взаимодействия.
Тогда можно менять механизм, не теряя знания.
Можно заменить программу другой. Можно использовать другой язык. Можно подключить искусственный интеллект. Можно изменить способ хранения.
Пока само знание существует отдельно и имеет понятную форму, оно остаётся собственностью системы или человека, а не конкретного приложения.
Но выносить наружу нужно не всё
Как и многие принципы Unix, эту идею легко превратить в догму.
Не нужно пытаться представить данными вообще весь код. Алгоритмы остаются алгоритмами. Проверка целостности, управление памятью, передача данных по сети, обработка ошибок и множество других задач естественно выражаются программой.
Вопрос нужно задавать там, где появляется изменяемое знание.
Это алгоритм или правило? Механизм или конкретное значение? Универсальное поведение или решение, которое завтра может измениться?
Если меняется содержание, а не сам механизм, возможно, перед нами данные.
Хорошая система переживает собственный код
Есть интересный способ проверить архитектуру.
Представим, что через пять лет текущей программы больше нет. Её переписали на другом языке, заменили другим продуктом или вообще разделили на несколько новых систем.
Что останется?
Если вместе с программой исчезают настройки, правила, структура, накопленные решения и смысл данных, значит слишком многое принадлежало коду.
Если же новое приложение может взять те же данные и продолжить работу, граница была проведена лучше.
Именно поэтому данные иногда оказываются важнее программы.
Программы приходят и уходят. Механизмы меняются. Инструменты становятся модными и устаревают.
А накопленная информация, правила и знания могут иметь ценность значительно дольше любого конкретного кода.

 Share








