
The post has been translated automatically. Original language: Russian



CRM creates a very convincing sense of order. The client has a card, a stage has been selected for the transaction, the amount has been filled in, a responsible person has been appointed, dates and tasks are set. Everything is laid out by fields, which means it seems that this data can be trusted.
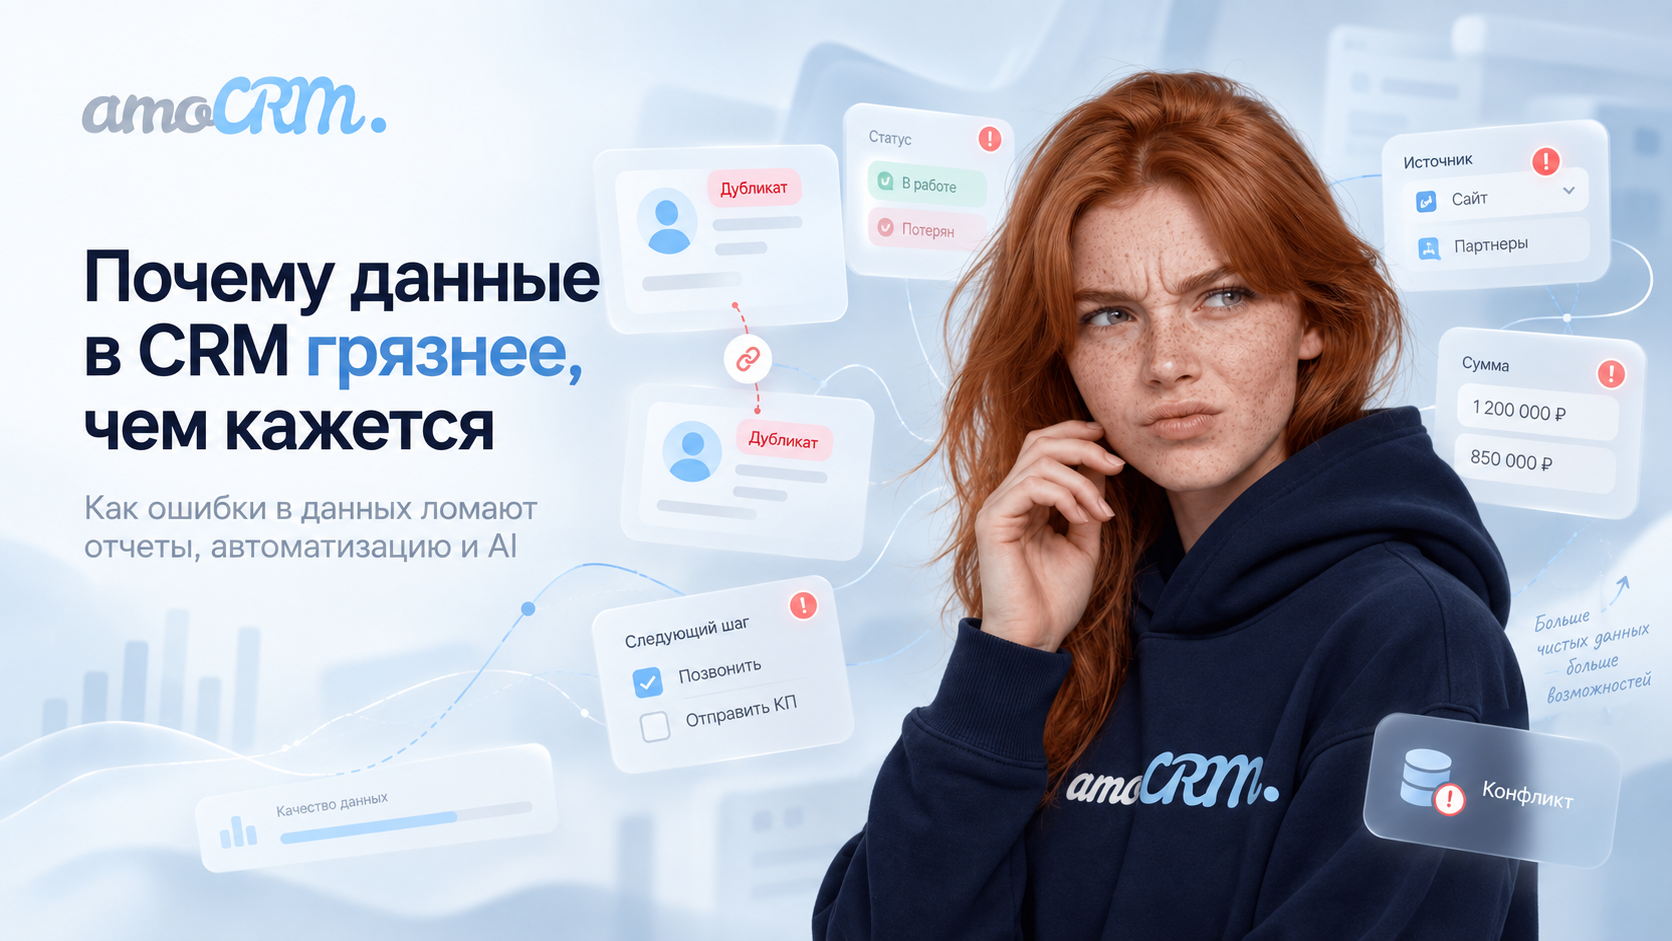
The problem is that most of the errors in CRM don't look like a mistake at all.
A phone with an extra digit is easy to spot. Much more dangerous is a field in which the correct value is written, but it is no longer relevant. Or two similar fields that employees understand slightly differently. The status can be selected correctly, although the real situation with the client has changed a long time ago.
Such data easily passes any checks, gets into reports, runs automatic scripts and becomes a context for AI.
At this point, a small inaccuracy ceases to live only inside one card.
The error may look completely normal.
Let's imagine that the CRM has a date for the next contact. The value is filled in, the format is correct, and the system is satisfied.
But where did this date come from?
Did the manager install it after talking to the client? Was it automatically transferred from the old task? Did the client then write to the chat and the agreement changed? Is there another field nearby with a similar meaning that is already being used by another process?
Everything is fine for the database. For a human, the value also looks convincing. The error will appear only when someone starts making a decision based on it.
A similar story happens with payments. The account's currency is stored in one place, and the currency of a specific operation is stored in another. The value itself is correct in both cases. If you confuse the meaning of the fields, the money suddenly starts getting into the wrong reports.
Even the word "paid" requires a definition. Has the invoice been issued? Has the client reported the payment? Has the money been received yet? Has an advance been made? Has the purchase been completed?
While CRM just stores information, such a difference can remain unnoticeable for a long time. As soon as analytics are available, the value of each field becomes part of the calculation.
Most of the dirt appears gradually
Usually, no one sits down in the morning to mess up the CRM.
The system develops together with the company. A new process appears, and an additional field is created for it. Then integration is connected and brings its own meaning. Another department needs similar information, but in a slightly different way. The old field can no longer be deleted, because automation is tied to it.
In a few years, there may well be two dates for the next contact, several ways to identify the person responsible, and three different signs that the customer has paid.
Each of them appeared at some point for an understandable reason.
A separate problem arises at the border of divisions. Sales, support, marketing, and finance look at the same customer from different angles. An agreement is important for the manager. For accounting - the fact of receipt of money. For marketing, it is the customer's source. For the manager, it's who the result belongs to in the end.
All these data can be correct at the same time, if it is clear in advance exactly what each of them means.
Without such definitions, CRM is gradually turning into a place where multiple versions of the same reality are stored.
A beautiful report easily hides bad data.
You can still see problems in individual cards. In aggregated analytics, they become almost invisible.
The dashboard shows 27%, 14 million, or 346 customers. The number looks accurate simply because it has two decimal places and a neat graph next to it.
At the same time, there may be old responsible persons, incorrect statuses, duplicates, transactions with another currency, or clients that the system counted twice.
The higher the level of aggregation, the more difficult it is to see the origin of the error.
Therefore, good analytics should allow you to go the other way. From the total figure, to the group, then to the manager, and from there to the specific clients and events from which this figure was collected.
This is useful not only for finding bugs.
If the indicator cannot be properly explained at the level of the initial data, it is difficult for the manager to make a decision even when the calculation is technically correct.
For example, the message "the manager has increased the number of problem clients" is almost useless without the ability to understand the reasons. A part may not have a next action. Someone has an overdue agreement. Someone has already paid an advance and was mistakenly included in the sample.
After disclosing the figure, it becomes clear whether there is a management problem there.
Automation makes data quality even more important.
Sometimes a person notices an oddity and stops.
The manager opens the card, sees the contradiction between the status and the last correspondence, and first understands the situation. The automatic script usually works differently: the condition is met, which means that the next action is triggered.
If the data is incorrect, the system may send an inappropriate message, move the transaction, change the person responsible, or set an unnecessary task.
The more processes that work without the participation of employees, the more expensive the bad source information becomes.
With AI, this dependence increases even more.
The model can understand free speech well, compare the history of communication and find connections between a large number of facts. But if the old status, the new agreement, and two fields with different values of the same entity are inside the CRM at the same time, the AI has another task: to understand what to believe from this.
A confident answer in a bad context is still a bad answer.
Therefore, before implementing complex AI scenarios, it is useful to understand rather boring things: what data is basic, where it comes from, how quickly it becomes obsolete, and what event can change it.
Fields without precise meaning are especially dangerous.
Many CRM systems have fields that everyone has been using for a long time, but different employees explain them in slightly different ways.
You can do a simple experiment. Select one important field and ask several people separately what exactly should be stored in it.
If the answers differ, the problem already exists.
It is even more useful to ask at what point the value should be updated. It turns out that agreeing on a name is often easier than agreeing on a data lifecycle.
Who changes the responsible person after the transfer of the client? What happens to the old value after payment? Do I need to clear the next date if the client contacted me earlier? How can I account for a refund? What is considered a new client after several years of absence?
It is from such small issues that large discrepancies in analytics are then collected.
The name of the field only answers the question of what was put there approximately. For normal operation, you also need to understand the source, the time of the update, and the rules by which the value ceases to be relevant.
CRM cleanliness does not mean that all fields are filled in.
Sometimes they try to improve the quality of data in the most obvious way: to make more fields mandatory.
As a result, there are actually fewer empty values.
Instead, "Other" appears, random dates, the first suitable option from the list, and values that the employee filled out just to save the card.
Formally, the database is getting cleaner. In terms of meaning, sometimes the opposite happens.
The lack of information is also information. If we don't know the date of the client's decision yet, an honest empty field is more useful than a fictitious date that will later be included in the forecast.
Therefore, commitment works well where the employee is really required to know the answer at this point in the process. In all other cases, it may simply mask the unknown.
It's not the cards that need to be cleaned, but the rules.
Periodic deduplication is useful. Old contacts should be updated, unnecessary fields should be removed, errors should be corrected.
But if the data logic itself remains the same, in a few months the database will return to approximately the same state.
It is much more useful to select key business entities and agree on where the source of truth for each of them is located. Where does the payment fact come from? How the current responsible person is determined. How the following arrangement is fixed. Which currency is used by a particular indicator. What exactly does each important status mean.
After that, you can see which processes are capable of changing these values and whether there are several systems that do this independently of each other.
A good CRM check doesn't require a lot of auditing at all. You can take twenty random clients and try to restore their history based on the system data alone.
Who is responsible for the client now? What's going on with him? When was the last meaningful contact? What have we agreed on? What should happen next? Did he pay and what exactly does CRM confirm this?
If you have to answer these questions with the words "it depends on which field to look at," the problem is already clear.
Data is not needed for the sake of order
A perfectly clean CRM most likely does not exist. People make mistakes, processes change, integrations are updated, new products and new ways of interacting with customers appear.
Therefore, the goal is not in a sterile database.
You need to understand which data really affects sales, automatic actions, analytics, and executive decisions. It is to them that the requirements should be particularly high.
A phone with a typo will ruin one call. An incorrectly determined source of truth can ruin a report for the entire department for months.
And the more a company trusts CRM to make decisions on its own, the more noticeable this difference becomes.
Good data is the data that the system and the person use to equally understand what is happening to the client right now.
CRM создаёт очень убедительное ощущение порядка. У клиента есть карточка, у сделки выбран этап, заполнена сумма, назначен ответственный, стоят даты и задачи. Всё разложено по полям, а значит кажется, что этим данным можно доверять.
Проблема в том, что значительная часть ошибок в CRM вообще не выглядит как ошибка.
Телефон с лишней цифрой заметить легко. Гораздо опаснее поле, в котором записано правильное значение, но оно уже неактуально. Или два похожих поля, которые сотрудники понимают немного по-разному. Статус тоже может быть выбран корректно, хотя реальная ситуация с клиентом давно изменилась.
Такие данные спокойно проходят проверки, попадают в отчёты, запускают автоматические сценарии и становятся контекстом для AI. После этого одна неточность уже начинает влиять на расчёты, действия системы и решения сотрудников.
Самые опасные ошибки не бросаются в глаза
Представим, что в CRM заполнена дата следующего контакта. Формат корректный, значение выглядит обычным, никаких предупреждений система не показывает.
Но откуда эта дата взялась?
Менеджер поставил её после разговора с клиентом? Она автоматически перенеслась из старой задачи? Клиент после этого написал в чат и договорённость изменилась? Есть ли рядом другое поле с похожим смыслом, которое использует уже другой процесс?
Для базы данных всё в порядке. Для человека значение тоже выглядит убедительно. Ошибка проявится только тогда, когда кто-нибудь начнёт принимать на его основе решение.
Похожая история бывает с оплатами. В одном месте хранится валюта аккаунта, в другом - валюта конкретной операции. Само значение в обоих случаях корректное. Если перепутать смысл полей, деньги начинают попадать не в те отчёты.
Даже слово «оплачен» требует определения. Счёт выставлен? Клиент сообщил об оплате? Деньги уже поступили? Внесён аванс? Покупка окончательно проведена?
Пока CRM просто хранит информацию, такая разница может долго оставаться незаметной. Как только появляется аналитика, значение каждого поля становится частью расчёта.
Большая часть грязи появляется постепенно
Обычно никто не садится утром с целью испортить CRM.
Система развивается вместе с компанией. Появляется новый процесс, для него создают дополнительное поле. Потом подключается интеграция и приносит своё значение. Другому отделу нужна похожая информация, но в немного другом виде. Старое поле уже нельзя удалить, потому что на него завязана автоматизация.
Через несколько лет рядом вполне могут существовать две даты следующего контакта, несколько способов определить ответственного и три разных признака того, что клиент заплатил.
Каждый из них когда-то появился по понятной причине.
Отдельная проблема возникает на границе подразделений. Продажи, поддержка, маркетинг и финансы смотрят на одного клиента с разных сторон. Для менеджера важна договорённость. Для бухгалтерии - факт поступления денег. Для маркетинга - источник клиента. Для руководителя - то, кому в итоге принадлежит результат.
Все эти данные могут быть правильными одновременно, если заранее понятно, что именно означает каждое из них.
Без таких определений CRM постепенно превращается в место, где хранится несколько версий одной реальности.
Красивый отчёт легко прячет плохие данные
В отдельных карточках проблемы ещё можно заметить. В агрегированной аналитике они становятся почти невидимыми.
Дашборд показывает 27%, 14 миллионов или 346 клиентов. Число выглядит точным просто потому, что у него есть два знака после запятой и аккуратный график рядом.
При этом внутри могут находиться старые ответственные, неверные статусы, дубли, сделки с другой валютой или клиенты, которых система посчитала дважды.
Чем выше уровень агрегации, тем сложнее увидеть происхождение ошибки.
Поэтому хорошая аналитика должна позволять пройти обратный путь. Из общей цифры - к группе, затем к менеджеру, а оттуда к конкретным клиентам и событиям, из которых эта цифра собралась.
Это полезно не только для поиска ошибок.
Если показатель нельзя нормально объяснить на уровне исходных данных, руководителю сложно принимать решение даже тогда, когда расчёт технически выполнен правильно.
Например, сообщение «у менеджера выросло количество проблемных клиентов» почти бесполезно без возможности понять причины. У части может не быть следующего действия. У кого-то просрочена договорённость. Кто-то уже оплатил аванс и вообще попал в выборку ошибочно.
После раскрытия цифры становится понятно, есть ли там управленческая проблема.
Автоматизация делает качество данных ещё важнее
Человек иногда замечает странность и останавливается.
Менеджер открывает карточку, видит противоречие между статусом и последней перепиской и сначала разбирается в ситуации. Автоматический сценарий обычно действует иначе: условие выполнено, значит запускается следующее действие.
Если данные неверные, система может отправить неуместное сообщение, передвинуть сделку, изменить ответственного или поставить ненужную задачу.
Чем больше процессов работает без участия сотрудников, тем дороже становится плохая исходная информация.
С AI эта зависимость усиливается ещё сильнее.
Модель может хорошо понимать свободную речь, сопоставлять историю общения и находить связи между большим количеством фактов. Но если внутри CRM одновременно лежат старый статус, новая договорённость и два поля с разным значением одной и той же сущности, перед AI появляется уже другая задача: понять, чему из этого верить.
Уверенный ответ на плохом контексте всё равно остаётся плохим ответом.
Поэтому перед внедрением сложных AI-сценариев полезно разобраться с довольно скучными вещами: какие данные являются основными, откуда они берутся, насколько быстро устаревают и какое событие может их изменить.
Особенно опасны поля без точного смысла
Во многих CRM есть поля, которыми все давно пользуются, но разные сотрудники объясняют их немного по-разному.
Можно провести простой эксперимент. Выбрать одно важное поле и отдельно спросить нескольких людей, что именно в нём должно храниться.
Если ответы отличаются, проблема уже существует.
Ещё полезнее спросить, в какой момент значение должно обновляться. Оказывается, что договориться о названии часто проще, чем договориться о жизненном цикле данных.
Кто меняет ответственного после передачи клиента? Что происходит со старым значением после оплаты? Нужно ли очищать следующую дату, если клиент сам вышел на связь раньше? Как учитывать возврат? Что считать новым клиентом после нескольких лет отсутствия?
Именно из таких мелких вопросов потом собираются большие расхождения в аналитике.
Название поля отвечает только на вопрос, что туда примерно положили. Для нормальной работы нужно ещё понимать источник, момент обновления и правила, по которым значение перестаёт быть актуальным.
Чистота CRM не означает, что все поля заполнены
Иногда качество данных пытаются улучшить самым очевидным способом: сделать больше полей обязательными.
В результате пустых значений действительно становится меньше.
Зато появляются «Другое», случайные даты, первый подходящий вариант из списка и значения, которые сотрудник заполнил только ради сохранения карточки.
Формально база становится чище. По смыслу иногда происходит обратное.
Отсутствие информации тоже является информацией. Если мы пока не знаем дату решения клиента, честное пустое поле полезнее выдуманной даты, которая потом попадёт в прогноз.
Поэтому обязательность хорошо работает там, где сотрудник действительно обязан знать ответ в этот момент процесса. Во всех остальных случаях она может просто маскировать неизвестность.
Чистить нужно не карточки, а правила
Периодическая дедупликация полезна. Старые контакты стоит обновлять, ненужные поля - убирать, ошибки - исправлять.
Но если сама логика данных остаётся прежней, через несколько месяцев база снова придёт примерно в то же состояние.
Гораздо полезнее выбрать ключевые бизнес-сущности и договориться, где находится источник истины для каждой из них. Откуда берётся факт оплаты. Как определяется текущий ответственный. Как фиксируется следующая договорённость. Какую валюту использует конкретный показатель. Что именно означает каждый важный статус.
После этого можно посмотреть, какие процессы способны менять эти значения и нет ли нескольких систем, которые делают это независимо друг от друга.
Хорошая проверка CRM вообще не требует большого аудита. Можно взять двадцать случайных клиентов и попытаться восстановить их историю только по данным системы.
Кто сейчас отвечает за клиента? Что с ним происходит? Когда был последний содержательный контакт? О чём договорились? Что должно случиться дальше? Платил ли он и что именно в CRM это подтверждает?
Если на эти вопросы приходится отвечать словами «смотря какое поле смотреть», проблема уже понятна.
Данные нужны не ради порядка
Идеально чистой CRM, скорее всего, не существует. Люди ошибаются, процессы меняются, интеграции обновляются, появляются новые продукты и новые способы взаимодействия с клиентами.
Цель поэтому не в стерильной базе.
Нужно понимать, какие данные действительно влияют на продажи, автоматические действия, аналитику и решения руководителей. Именно к ним требования должны быть особенно высокими.
Телефон с опечаткой испортит один звонок. Неверно определённый источник истины способен месяцами портить отчёт для всего отдела.
И чем больше компания доверяет CRM принимать решения самостоятельно, тем заметнее становится эта разница.
Хорошие данные - это данные, по которым система и человек одинаково понимают, что сейчас происходит с клиентом.
 Share