
The post has been translated automatically. Original language: Russian



In a monolith with a single database, a multistep business operation usually fits into a single ACID transaction: if something goes wrong at any step, the DBMS rolls back everything at once. In a microservice architecture where each service owns its own database, this convenience is no longer there — an operation like "apply for a loan" may involve a scoring service, a limit reservation service, and a notification service, each with its own database, and a single transaction that will roll back changes in all three at once simply does not exist.
The classic solution from the world of distributed systems is a two—phase commit (2PC), but in practice it does not work well with microservices: it requires all participants in a transaction to remain locked and accessible until completion, which dramatically reduces fault tolerance and throughput, and any temporarily unavailable participant blocks the entire operation.
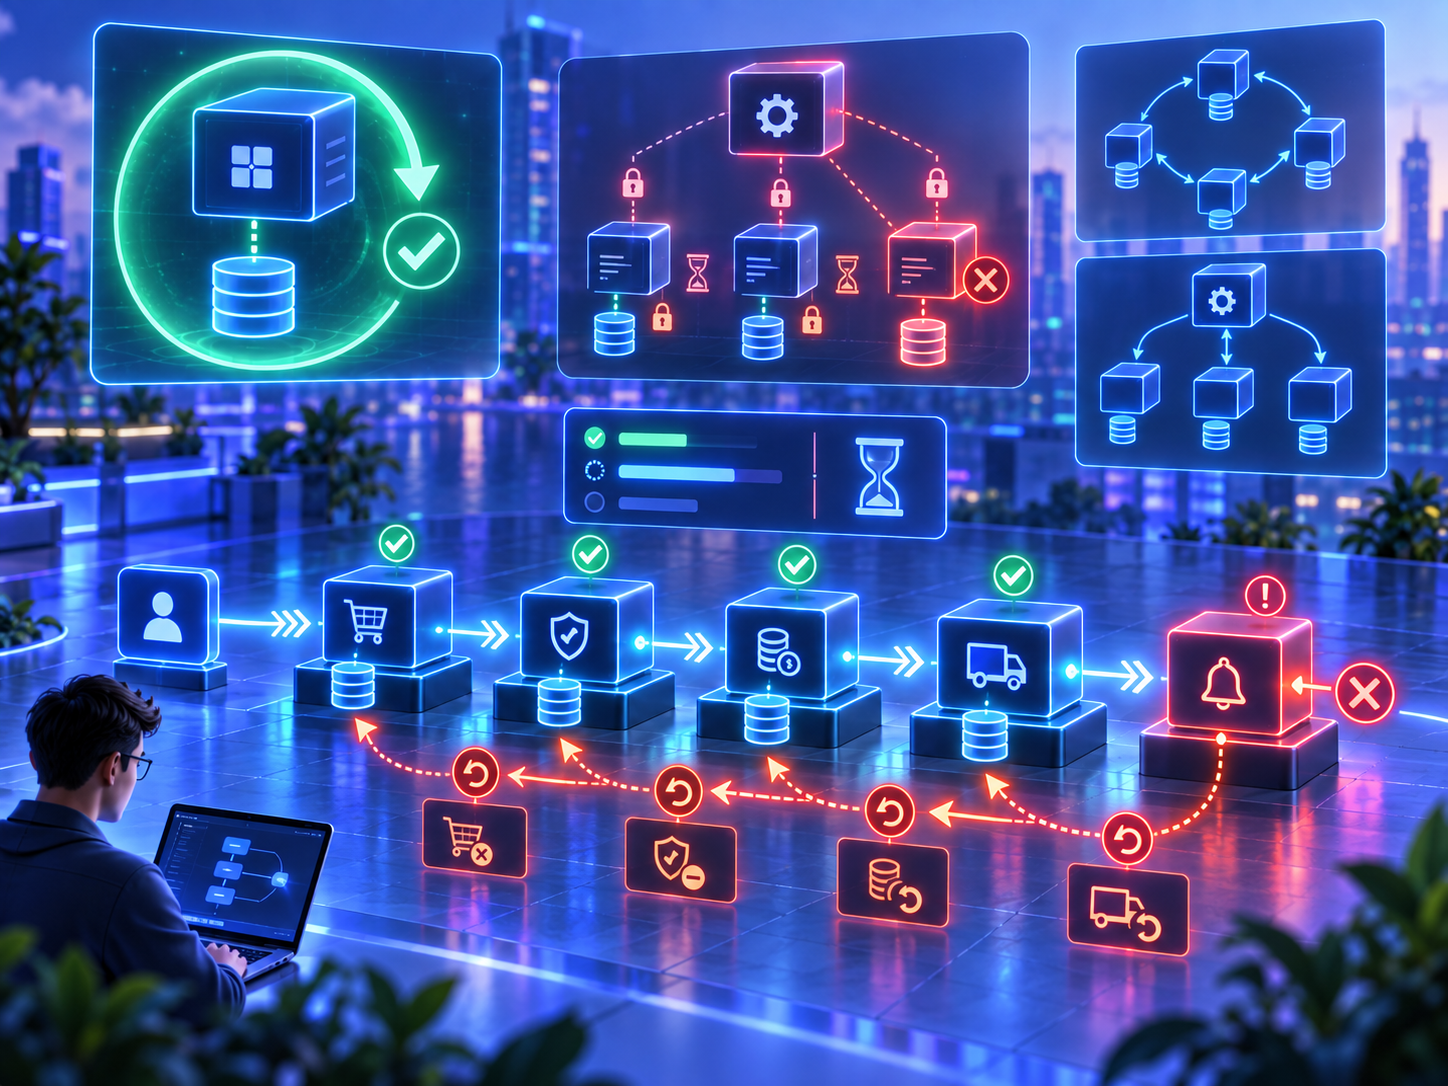
The Saga pattern offers a different approach: instead of one large transaction, there is a sequence of local transactions, each in its own service and database, and for each step a compensating operation is pre—defined — an action that cancels the effect of the step if something goes wrong in one of the following steps. If the limit reservation was successful, but the notification could not be sent to the partner definitively after all the delays, the saga does not try to "finish" the notification at any cost, but starts the compensation chain in reverse order — for example, it removes the reserve limit that was set earlier.
The pattern has two main organization options. The choreographic approach is that each service publishes an event about the completion of its step, and the next service in the chain reacts to this event itself, without a central coordinator; it's simple at the start, but as the number of steps increases, it becomes difficult to follow the logic of the entire saga — it's spread across event handlers in different services. The orchestrative approach is a dedicated coordinator who explicitly calls each step in turn and knows the entire sequence, including compensation; this is clearer and easier to debug, but adds a separate component that itself must be reliable.
The key feature that is easy to miss is that the saga does not provide strict isolation in the spirit of ACID: between steps, the system is in an intermediate state for some time, visible from the outside (the limit has already been reserved, but the application has not yet been confirmed), and you need to consciously work with this at the UI and business logic level, not pretend that a distributed operation looks like an instant atomic transaction to the user.
В монолите с одной базой данных многошаговая бизнес-операция обычно укладывается в одну ACID-транзакцию: если что-то на любом шаге пошло не так, СУБД откатывает всё разом. В микросервисной архитектуре, где каждый сервис владеет собственной базой, этого удобства уже нет — операция вроде «оформить заявку на заём» может затрагивать сервис скоринга, сервис резервирования лимита и сервис уведомлений, каждый со своей БД, и единой транзакции, которая откатит изменения во всех трёх сразу, попросту не существует.
Классическое решение из мира распределённых систем — двухфазный коммит (2PC), но на практике он плохо уживается с микросервисами: требует, чтобы все участники транзакции оставались в режиме ожидания и сохраняли доступность до самого завершения, что резко снижает отказоустойчивость и пропускную способность, а любой временно недоступный участник останавливает всю операцию целиком.
Паттерн Saga предлагает другой подход: вместо одной большой транзакции — последовательность локальных транзакций, каждая в своём сервисе и своей БД, и для каждого шага заранее определена компенсирующая операция — действие, которое отменяет эффект шага, если что-то на одном из следующих шагов пойдёт не так. Если резервирование лимита прошло успешно, а уведомление партнёру отправить не удалось окончательно после всех ретраев, сага не пытается «докрутить» уведомление любой ценой, а запускает цепочку компенсаций в обратном порядке — например, снимает резерв лимита, который был поставлен ранее.
У паттерна есть два основных варианта организации. Хореографический подход — каждый сервис публикует событие о завершении своего шага, а следующий сервис в цепочке сам на это событие реагирует, без центрального координатора; это просто на старте, но с ростом числа шагов становится сложно проследить логику всей саги целиком — она размазана по обработчикам событий в разных сервисах. Оркестрационный подход — есть выделенный координатор, который явно вызывает каждый шаг по очереди и знает всю последовательность целиком, включая компенсации; это нагляднее и проще отлаживать, но добавляет отдельный компонент, который сам должен быть надёжным.
Ключевая особенность, которую легко упустить, — сага не даёт строгой изоляции в духе ACID: между шагами система на какое-то время находится в промежуточном состоянии, видимом снаружи (лимит уже зарезервирован, но заявка ещё не подтверждена), и с этим нужно осознанно работать на уровне UI и бизнес-логики, а не притворяться, что распределённая операция выглядит для пользователя как мгновенная атомарная транзакция.
 Share