

The post has been translated automatically. Original language: Russian



I'm making VYUD Studio— an AI course builder that works inside Telegram. The expert sends his material, and the model breaks it down into modules, lessons, and quizzes.
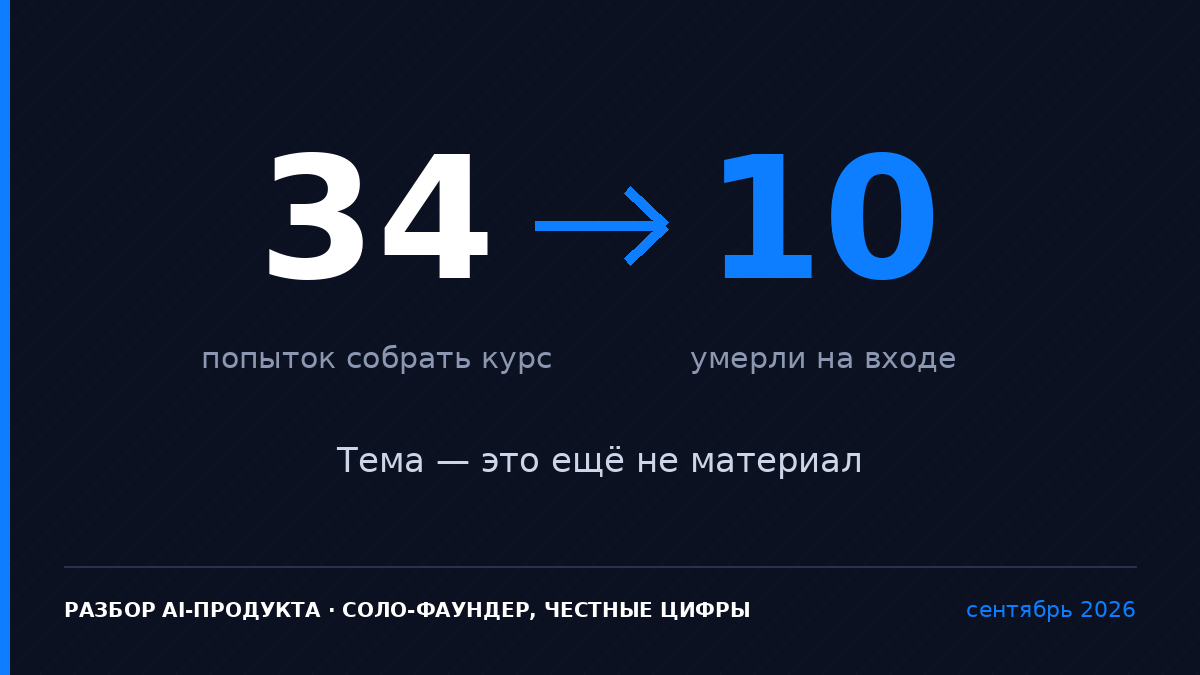
In the product admin panel on September 29th: 34 attempts to assemble the course. 10 of them died before they started. All ten have one mistake — "Too little material": there are less than two hundred characters in the input.
This is almost every third attempt. Not a bug or a model failure. The person came, wrote, and left after the first message.
The analysis will be useful to anyone whose AI product runs on user data or knowledge: course generators, document assistants, knowledge base RAG bots, upload analytics. Everyone has the same problem, it's just that I have it in numbers.
What is visible in the data
A painting for one day:
- 76 people reached the product;
- The course build was launched 34 times: 24 generations passed, 10 dropped at the entrance;
- 13 courses have been published.
A noticeable part of the gap between 76 and 13 is not in the editor or in the publication, but in the very first message.
Two errors came on September 28 at night — at 00:03 and at 04:53. Someone alive was awake, tried and failed. I remember these two lines in the log better than any percentage.
Topic versus Material
You can see what people sent by the size: one line. "Sales". "Python for beginners". "Fundamentals of negotiations".
The generator does not add knowledge — it decomposes yours. They brought the headline — there's nothing to collect it from.
The working rule that I've deduced is that if what you're sending fits in the header, it's still a topic. The material does not fit in the title.
The material is a two—minute voice message ("explain how to a colleague over coffee"), your post or article in its entirety — in text, not a link, a piece of a tutorial or a summary — a page is enough.
The product accepts all of this from day one: voice, video, document, text. And still, almost a third of the attempts are a line.
Why do users do this?
ChatGPT has taught us all: a short request is a long response, as if the model knows everything by itself. A person comes to a new AI product with this habit and writes a topic.
And a product built on user knowledge works the other way around. Its value is that the result is collected from your expertise, and not from the average Internet. This means that knowledge is needed at the entrance, not a request.
I was building a product with one model in my head, the user came from another, and the first screen didn't explain the difference to him. It's not "users don't read." This is the onboarding that I didn't do.
Where the output is stronger than the data
The temptation is to say, "I'll fix the entrance, and there will be twice as many courses." Must not.
10 out of 34 are attempts, not people: one person could fall three times and then send a normal text. I haven't checked how many unique people are behind these ten. The sample is small and for one date — the problem is obvious, the size cannot be measured. And the entrance is the most visible hole, but not the only one: after assembling the course, there are still steps before publication.
Therefore, "fixing the entrance first" is the right decision: the cheapest place with the most understandable reason. And "input is the main problem of the product" is still a hypothesis.
What I changed
The appeal is in all posts. It was "write a topic to the bot", it became "send a voicemail for two minutes" or "insert your entire post". If marketing teaches you to send a theme, the product will receive a theme.
The first screen. He should not teach buttons, but one difference: the theme versus the material. Voice is the first option: this is the only format where the expert does not hang out. Anyone can talk about their business for two minutes, but not a page of text from scratch.
The criterion is before the test, not after. Currently, the failure rate of "little material" is about 29%. If it doesn't fall below 15% in a month, it's not about the wording, but about the input itself.
Honest postscript: I can't check the criterion right now — my measurement has been broken for the fourth week. I've been publishing for two weeks in a row without a single glitch, but I don't see any returns. Automated the exit earlier than the feedback. This is a separate analysis.
Three rules worth picking up for yourself
1. The entrance is more expensive than the showcase. The landing page, price, and payment don't matter if the person left on the first step. Watch the funnel from the beginning, not from the checkout.
2. If the product is based on the user's knowledge, the first thing you sell is an understanding of what they need to bring. The model can structure the expertise. Fake it, no.
3. Marketing is also onboarding. As you call into the product, so they come into it.
I don't do these kinds of reviews only at home. If users in your AI product leave at the first step or bring "the wrong thing", I have an hour-long consultation on AI development in the Hub Market: tools, workflow, multi—agents. It usually takes an hour to see exactly where the entrance is being torn.
Я делаю VYUD Studio — AI-конструктор курсов, который работает внутри Telegram. Эксперт присылает свой материал, модель раскладывает его на модули, уроки и квизы.
В админке продукта на 29 сентября: 34 попытки собрать курс. 10 из них умерли, не начавшись. У всех десяти одна ошибка — «Too little material»: на входе меньше двухсот символов.
Это почти каждая третья попытка. Не баг и не сбой модели. Человек пришёл, написал — и ушёл после первого сообщения.
Разбор пригодится всем, чей AI-продукт работает на данных или знаниях пользователя: генераторы курсов, ассистенты по документам, RAG-боты по базе знаний, аналитика по выгрузкам. Проблема у всех одна и та же, просто у меня она оказалась в цифрах.
Что видно в данных
Картина на один день:
- 76 человек дошли до продукта;
- 34 раза запустили сборку курса: 24 генерации прошли, 10 упали на входе;
- 13 курсов опубликовано.
Заметная часть разрыва между 76 и 13 сидит не в редакторе и не в публикации, а в самом первом сообщении.
Две ошибки пришли 28 сентября ночью — в 00:03 и в 04:53. Кто-то живой не спал, попробовал и не смог. Эти две строчки в логе я запомнил лучше любых процентов.
Тема против материала
Что присылали люди, видно по размеру: одна строчка. «Продажи». «Питон для начинающих». «Основы переговоров».
Генератор не добавляет знание — он раскладывает ваше. Принесли заголовок — собирать не из чего.
Рабочее правило, которое я вывел: если то, что вы отправляете, помещается в заголовок, — это ещё тема. Материал в заголовок не помещается.
Материал — это голосовое на две минуты («объясните, как коллеге за кофе»), свой пост или статья целиком — текстом, а не ссылкой, кусок методички или конспекта — страницы достаточно.
Продукт принимает всё это с первого дня: голос, видео, документ, текст. И всё равно почти треть попыток — строчка.
Почему пользователи так делают
Нас всех выучил ChatGPT: короткий запрос — длинный ответ, модель как будто знает всё сама. Человек приходит в новый AI-продукт с этой привычкой и пишет тему.
А продукт, построенный на знании пользователя, устроен наоборот. Его ценность — что результат собран из вашей экспертизы, а не из усреднённого интернета. Значит, на входе нужно знание, а не запрос.
Я строил продукт с одной моделью в голове, пользователь пришёл с другой, и первый экран ему разницу не объяснил. Это не «пользователи не читают». Это онбординг, который я не сделал.
Где вывод сильнее данных
Соблазн — сказать «починю вход, и курсов станет вдвое больше». Нельзя.
10 из 34 — это попытки, а не люди: один человек мог упасть трижды, а потом прислать нормальный текст. Сколько за этими десятью уникальных людей, я не проверял. Выборка маленькая и на одну дату — проблему видно, размер не измерить. И вход — самая видимая дыра, но не единственная: после сборки курса ещё есть шаги до публикации.
Поэтому «чинить вход первым» — верное решение: самое дешёвое место с самой понятной причиной. А «вход — главная проблема продукта» — пока гипотеза.
Что я поменял
Призыв во всех постах. Было «напишите боту тему», стало «пришлите голосовое на две минуты» или «вставьте свой пост целиком». Если маркетинг учит присылать тему, продукт получит тему.
Первый экран. Он должен учить не кнопкам, а одному различию: тема против материала. Голос — первым вариантом: это единственный формат, где эксперт не зависает. Две минуты про своё дело наговорит кто угодно, страницу текста с нуля — нет.
Критерий — до теста, а не после. Сейчас доля отказов «мало материала» — около 29%. Если через месяц она не опустится ниже 15%, дело не в формулировках, а в самом входе.
Честная приписка: проверить критерий прямо сейчас я не могу — четвёртую неделю у меня сломано измерение. Публикую я две недели подряд без единого сбоя, а отдачу не вижу. Автоматизировал выход раньше, чем обратную связь. Это отдельный разбор.
Три правила, которые стоит забрать себе
1. Вход дороже витрины. Лендинг, цена и оплата не имеют значения, если человек ушёл на первом шаге. Смотрите воронку с начала, а не с кассы.
2. Если продукт работает на знании пользователя, первое, что вы продаёте, — понимание, что ему нужно принести. Модель может структурировать экспертизу. Подделать её — нет.
3. Маркетинг — это тоже онбординг. Как вы зовёте в продукт, так в него и приходят.
Такие разборы я делаю не только у себя. Если в вашем AI-продукте пользователи уходят на первом шаге или приносят «не то», — в Hub Market у меня есть часовая консультация по AI-разработке: инструменты, workflow, мультиагенты. За час обычно видно, где именно рвётся вход.
 Share





