
The post has been translated automatically. Original language: Russian




We make a service that monitors the cashiers in restaurants and immediately informs the owner if something happens: they opened a shift, removed an item from the receipt, and gave a big discount. Now there are about five thousand cash registers in different countries. While there were a couple hundred cash registers, everything worked by itself. With the growth, the surprises began. Here are the three that I remember the most.
Friday night
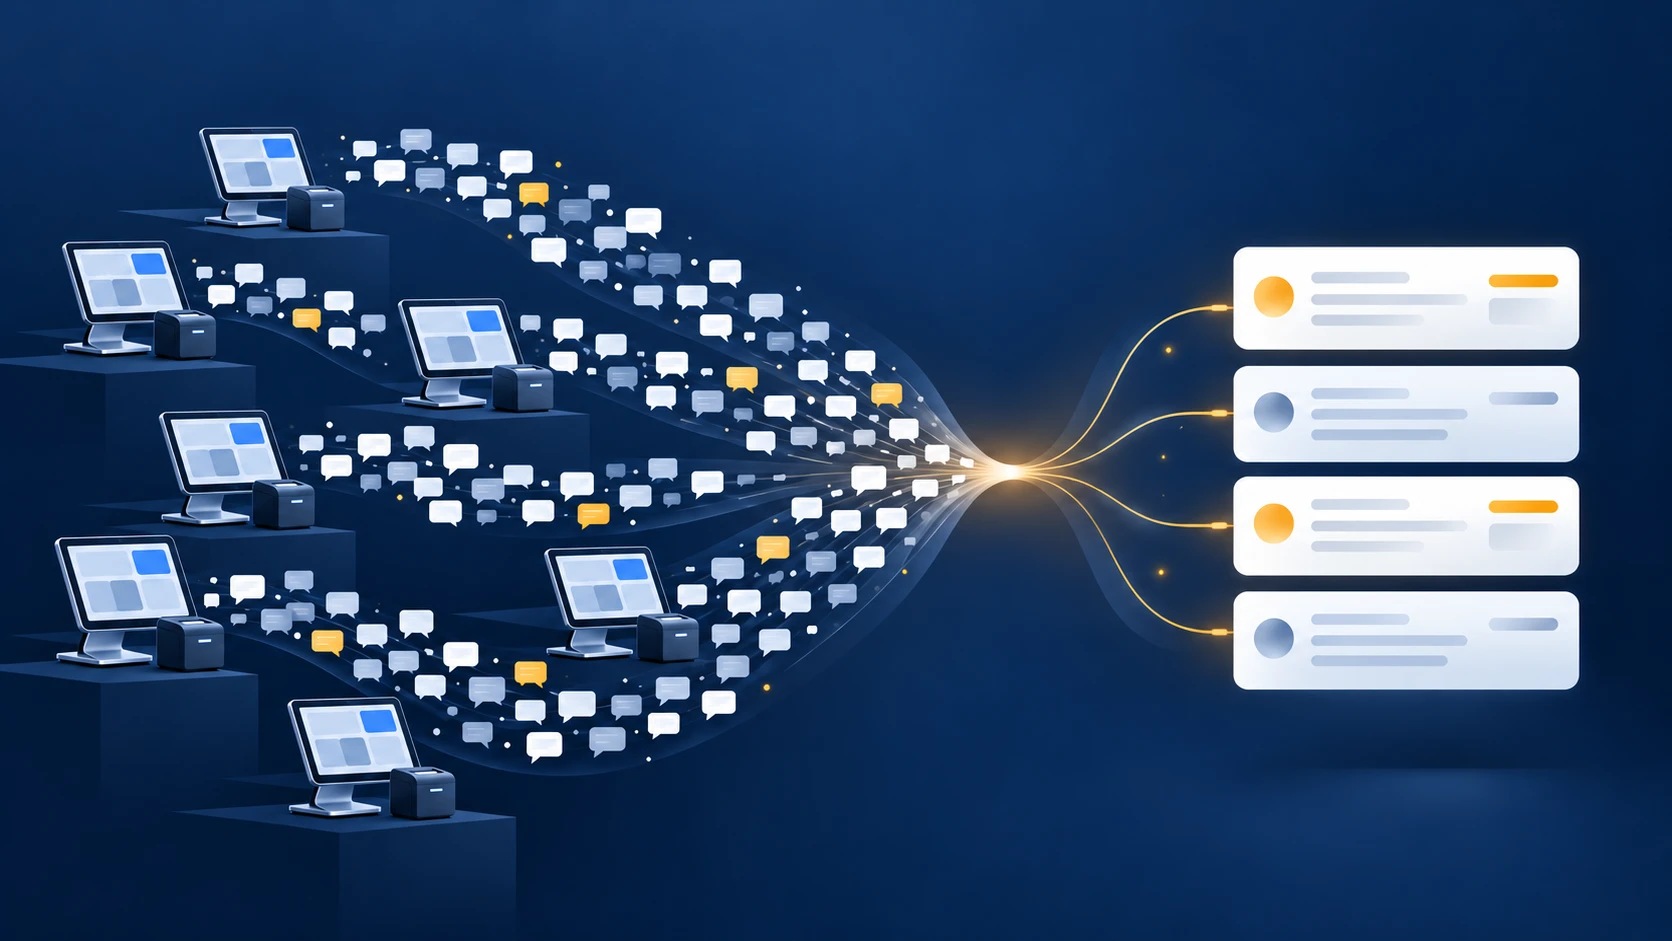
We send notifications via messenger, and messenger has a limit of about 30 messages per second. For a long time, we didn't even think about him. And then came the usual Friday night, when almost all restaurants close shifts at the same time. There were more messages than the limit allowed, the server started responding "wait", and some of the notifications arrived several minutes late.
The priority queue helped: the important things go first, and now we collect the same type of events into one summary message. It's even more convenient for the owner than twenty separate lines.
The numbers are over
Each event in our database receives an ordinal number. A long time ago, we chose an ordinary integer for it, which is a little more than two billion. It seemed like it would be enough forever. It wasn't enough: one day, in the middle of the working day, new events simply stopped being recorded.
It would not be possible to quickly change the type on a table with hundreds of millions of rows, it would take too much time. Therefore, we created a new table with "long" numbers nearby and switched to it. Now, for any logs, we immediately take 64-bit numbers and see how many are left.
What time is it now
We have a server in one time zone, a developer in another, and clients in several more. There is one time in the log file name, another time inside the record, and a third time in the file on the network drive. One day, I spent half a day looking for a problem that didn't exist: I was just comparing records with a two-hour difference.
Since then, the rule has been simple: we write the time in the logs with an explicit indication of the zone, and preferably immediately in UTC.
What have you learned from this
Almost all of our surprises were caused not by errors in the code, but by growth. What works fine on hundreds of cash registers breaks down on thousands. So now we ask ourselves in advance: what happens if the load increases tenfold? The answer to this question is usually cheaper than another Friday night.
Мы делаем сервис, который следит за кассами в ресторанах и сразу сообщает владельцу, если что-то происходит: открыли смену, удалили позицию из чека, дали большую скидку. Сейчас это около пяти тысяч касс в разных странах. Пока касс было пару сотен, всё работало само. С ростом начались сюрпризы. Вот три, которые запомнились больше всего.
Пятничный вечер
Уведомления мы отправляем через мессенджер, а у мессенджера есть лимит: примерно 30 сообщений в секунду. Долгое время мы о нём даже не вспоминали. А потом наступил обычный пятничный вечер, когда почти все рестораны закрывают смены в одно и то же время. Сообщений стало больше, чем пропускает лимит, сервер начал отвечать «подождите», и часть уведомлений пришла с опозданием в несколько минут.
Помогла очередь с приоритетами: важное уходит первым, а однотипные события мы теперь собираем в одно сообщение-сводку. Владельцу так даже удобнее, чем двадцать отдельных строчек.
Номера закончились
Каждое событие у нас в базе получает порядковый номер. Когда-то давно мы выбрали для него обычное целое число, это чуть больше двух миллиардов. Казалось, хватит навсегда. Не хватило: однажды посреди рабочего дня новые события просто перестали записываться.
Быстро поменять тип на таблице с сотнями миллионов строк не получилось бы, это заняло бы слишком много времени. Поэтому мы создали рядом новую таблицу с «длинными» номерами и переключились на неё. Теперь для любых журналов сразу берём 64-битные номера и следим, сколько их осталось.
Сколько сейчас времени
Сервер у нас в одном часовом поясе, разработчик в другом, клиенты ещё в нескольких. В имени файла журнала одно время, внутри записи другое, у файла на сетевом диске третье. Однажды я полдня искал проблему, которой не было: просто сравнивал записи с разницей в два часа.
С тех пор правило простое: время в журналах пишем с явным указанием пояса, а лучше сразу в UTC.
Что из этого вынесли
Почти все наши сюрпризы появились не из-за ошибок в коде, а из-за роста. То, что прекрасно работает на сотне касс, ломается на тысячах. Поэтому теперь мы заранее спрашиваем себя: а что будет, если нагрузка вырастет в десять раз? Ответ на этот вопрос обычно дешевле, чем очередной пятничный вечер.
 Share