



The post has been translated automatically. Original language: Russian





When a program compiles without errors, it does not mean that it is working correctly. Even if all the tests pass, the question remains: have we really checked everything that is important, or only those situations that we have foreseen in advance?
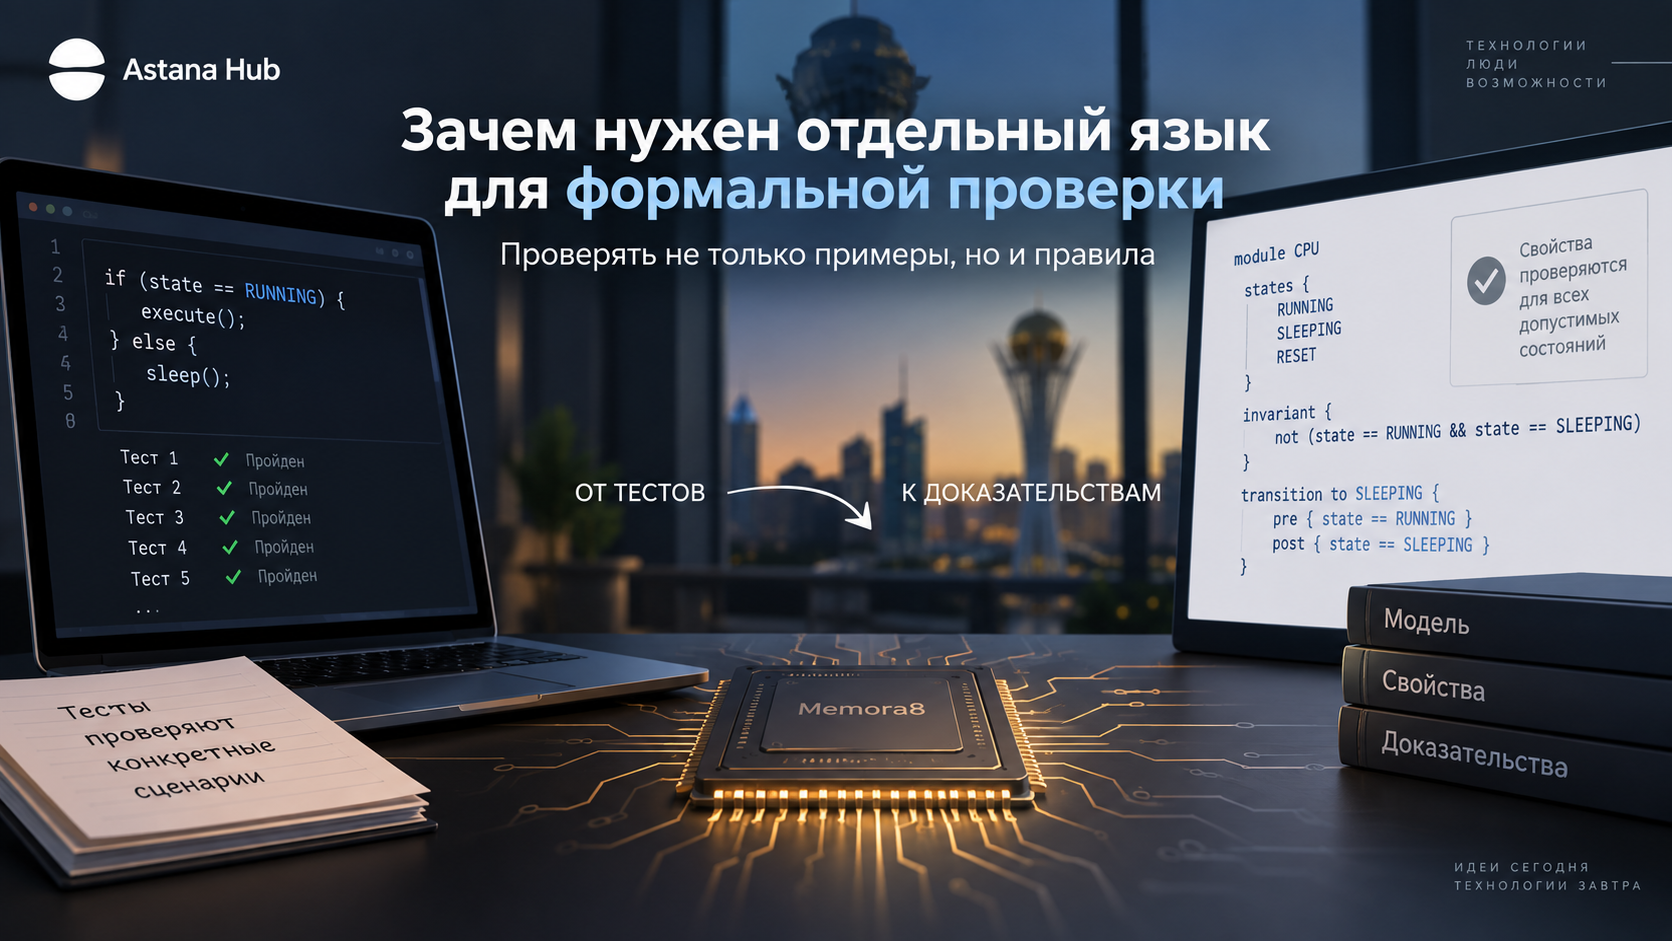
In normal development, tests remain the main verification method. We set the input data, run the program, and see if the result meets expectations. This approach works well, but it has a natural limitation: each test checks only a specific scenario or a small group of scenarios.
If a system can be in thousands or millions of different states, it is almost impossible to check each of them with a separate test. This problem is especially noticeable in the development of processors, devices, control systems, and other software, where an error can occur only with a rare combination of several conditions.
Check not only the examples, but also the rules.
Formal verification offers a different approach. Instead of checking only individual examples of how the program works, you can formulate a rule that should always be followed, and then try to prove that the system cannot violate it.
""For example, instead of the test "let's give the system such data and look at the result," you can set a requirement: "when these conditions are met, the system should never go into such a state." After that, a special program examines the possible states of the system and tries to find a violation of this requirement.
But here the following question arises: where and how to describe such rules? They can be embedded directly into the source code, written using additional constructs of an existing language, or included in a separate description.
In our case, we decided to check the last option. This is how SJV appeared, a small language designed to describe states, transitions, and properties that need to be checked.
Why not write everything in one language
At first glance, a separate language seems like an unnecessary complication. There is already a source program, so it is logical to ask: why create another recording method?
The reason is that the source code and the verification description answer different questions. The source code defines what the system should do, and the verification description sets boundaries that the system should not violate.
Let's say the program manages the processor state and contains the transition code between the operating state and the standby state. In this case, completely different statements may be important for verification: the processor should not be in two states at the same time, a certain operation should be performed only in operating mode, and after a specific command, some values must change, while others must remain the same.
This is no longer a description of the algorithm. This is a description of the conditions under which we consider his work to be correct.
This separation allows you not to confuse the implementation with the requirements for it. In addition, the rules themselves become more noticeable: they can be read and discussed separately from the program code.
What it looks like in SJV
The current version of SJV is intentionally kept small. First, the module that needs to be checked is specified, and then the acceptable states and the rules for transitions between them are described.
For a function, you can specify the conditions that must be met before it is executed, and the requirements for the state after completion. As a result, the verification description is based around several simple questions: what state the system may be in, under what conditions the action is allowed, and what should be true after this action.
At the same time, SJV should not turn into a second implementation of the program. If the verification description starts repeating the entire original algorithm in a different syntax, a new problem arises: now you need to figure out which of the two implementations is correct.
Therefore, one of the main ideas of the approach is to describe not the algorithm itself, but its limitations and properties. The source code tells you how to perform the action, and the SJV tells you what conditions cannot be violated when performing it.
Checking on a real system
SJV did not appear as a completely abstract experiment. We use it when developing Memora8, our own processor architecture.
The processor turned out to be a convenient object for such work, because it has many states, memory access rules, transitions between modes, and interactions between components. However, an error in one small rule can manifest itself far from the place where it originated.
For example, you can write a regular test that checks one specific memory request. But a more general rule can be formulated: if a certain area of memory belongs to one processor, another processor should not access it until it is released.
The task of the verification system in this case is to find a sequence of actions in which this rule is violated. If such an option exists, we get a specific error example. If it is impossible to find it within the framework of a given model, the property is considered proven for this model.
This is an important difference from simply increasing the number of tests. We are trying to check not more and more individual examples, but the rules of the system itself.
Why separate the verification from the program language?
A separate description has another potential advantage. The rule of operation of a system is not always related to the specific language in which it is implemented.
For example, the requirement "after reset, the device must be in the initial state" applies to the device itself. It doesn't matter if it's described in SystemVerilog, another hardware description language, or implemented in a different way.
If the verification model is separated from the source code, it becomes possible to save the rules when the implementation changes. Theoretically, this also allows you to use a single way of describing requirements for multiple languages.
However, supporting a large number of languages is not our goal in itself. Now it is more important to understand in which real-world tasks such separation really benefits and how convenient it is to use it on existing projects.
Formal verification also has limits
A formal check does not mean that the program can be declared absolutely correct after it. Any proof applies only to the requirements and the model that have been specified.
If the developer forgot to formulate an important rule, the system will not check it. If the environment is incorrectly described or an incorrect assumption is made about the behavior of one of the components, the formally correct result may also be of little use.
Therefore, this approach is not a substitute for testing, code analysis, and engineering understanding of the system. It adds another verification method, which is especially useful where it is possible to formulate the required properties accurately enough.
What we want to find out
As a complex system grows, it becomes increasingly difficult to keep its rules only in the minds of developers, documentation, and a large set of tests. It makes sense to write down some of these rules in a form that can not only be read, but also automatically checked.
In this approach, the source code is responsible for the behavior of the system, the tests check the selected scenarios, and the formal model answers another question: is there a generally acceptable sequence of actions that will lead the system to a prohibited state?
It is to solve this problem that we are experimenting with SJV. Right now, it is important for us not to prove that a separate verification language is suitable for everything, but to define the boundaries of its usefulness: where it really simplifies development and detects errors that are difficult to find by conventional means, and where it only adds another level of complexity to the system.
Когда программа компилируется без ошибок, это ещё не означает, что она работает правильно. Даже если все тесты проходят, остаётся вопрос: проверили ли мы действительно всё важное или только те ситуации, которые заранее предусмотрели?
В обычной разработке основным способом проверки остаются тесты. Мы задаём входные данные, запускаем программу и смотрим, соответствует ли результат ожиданиям. Такой подход хорошо работает, но у него есть естественное ограничение: каждый тест проверяет только конкретный сценарий или небольшую группу сценариев.
Если система может находиться в тысячах или миллионах различных состояний, проверить каждое из них отдельным тестом практически невозможно. Особенно заметна эта проблема при разработке процессоров, устройств, систем управления и другого программного обеспечения, где ошибка может проявиться только при редком сочетании нескольких условий.
Проверять не только примеры, но и правила
Формальная проверка предлагает другой подход. Вместо того чтобы проверять только отдельные примеры работы программы, можно сформулировать правило, которое должно выполняться всегда, а затем попытаться доказать, что система не может его нарушить.
Например, вместо теста «передадим системе такие данные и посмотрим на результат» можно задать требование: «при выполнении этих условий система никогда не должна переходить в такое состояние». После этого специальная программа рассматривает возможные состояния системы и пытается найти нарушение этого требования.
Но здесь появляется следующий вопрос: где и как описывать такие правила? Их можно встроить непосредственно в исходный код, записывать с помощью дополнительных конструкций существующего языка или вынести в отдельное описание.
В нашем случае мы решили проверить последний вариант. Так появился SJV — небольшой язык, предназначенный для описания состояний, переходов и свойств, которые нужно проверить.
Почему не писать всё на одном языке
На первый взгляд отдельный язык кажется лишним усложнением. Уже есть исходная программа, поэтому логично спросить: зачем создавать ещё один способ записи?
Причина в том, что исходный код и описание проверки отвечают на разные вопросы. Исходный код определяет, что система должна делать, а описание проверки задаёт границы, которые система при этом не должна нарушать.
Допустим, программа управляет состоянием процессора и содержит код перехода между рабочим состоянием и состоянием ожидания. Для проверки при этом могут быть важны совсем другие утверждения: процессор не должен одновременно находиться в двух состояниях, определённая операция должна выполняться только в рабочем режиме, а после конкретной команды некоторые значения обязаны измениться, тогда как другие должны остаться прежними.
Это уже не описание алгоритма. Это описание условий, при которых мы считаем его работу правильной.
Такое разделение позволяет не смешивать реализацию с требованиями к ней. Кроме того, сами правила становятся заметнее: их можно читать и обсуждать отдельно от кода программы.
Как это выглядит в SJV
Текущая версия SJV намеренно остаётся небольшой. Сначала указывается модуль, который требуется проверить, а затем описываются допустимые состояния и правила переходов между ними.
Для функции можно задать условия, которые должны выполняться до её выполнения, и требования к состоянию после завершения работы. В результате описание проверки строится вокруг нескольких простых вопросов: в каком состоянии система может находиться, при каких условиях разрешено действие и что должно быть истинно после этого действия.
При этом SJV не должен превращаться во вторую реализацию программы. Если проверочное описание начинает повторять весь исходный алгоритм другим синтаксисом, возникает новая проблема: теперь уже нужно выяснять, какая из двух реализаций правильная.
Поэтому одна из основных идей подхода состоит в том, чтобы описывать не сам алгоритм, а его ограничения и свойства. Исходный код говорит, как выполнить действие, а SJV — какие условия нельзя нарушить при его выполнении.
Проверка на реальной системе
SJV появился не как полностью отвлечённый эксперимент. Мы используем его при разработке Memora8 — собственной архитектуры процессора.
Процессор оказался удобным объектом для такой работы, потому что в нём много состояний, правил доступа к памяти, переходов между режимами и взаимодействий между компонентами. При этом ошибка в одном небольшом правиле может проявиться далеко от того места, где она возникла.
Например, можно написать обычный тест, который проверит один конкретный запрос к памяти. Но можно сформулировать более общее правило: если определённая область памяти принадлежит одному процессору, другой процессор не должен получить к ней доступ до её освобождения.
Задача системы проверки в таком случае — найти последовательность действий, при которой это правило нарушается. Если такой вариант существует, мы получаем конкретный пример ошибки. Если его найти невозможно в рамках заданной модели, свойство считается доказанным для этой модели.
Это важное отличие от простого увеличения количества тестов. Мы пытаемся проверять не всё больше отдельных примеров, а сами правила устройства системы.
Зачем отделять проверку от языка программы
У отдельного описания есть ещё одно потенциальное преимущество. Правило работы системы не всегда связано с конкретным языком, на котором она реализована.
Например, требование «после сброса устройство должно находиться в начальном состоянии» относится к самому устройству. Не так важно, описано оно на SystemVerilog, другом языке описания аппаратуры или реализовано иным способом.
Если проверочная модель отделена от исходного кода, появляется возможность сохранить правила при изменении реализации. Теоретически это также позволяет использовать один способ описания требований для нескольких языков.
Однако поддержка большого количества языков сама по себе не является нашей целью. Сейчас важнее понять, в каких реальных задачах такое разделение действительно приносит пользу и насколько удобно использовать его на существующих проектах.
Формальная проверка тоже имеет границы
Формальная проверка не означает, что программу после неё можно объявить абсолютно правильной. Любое доказательство относится только к тем требованиям и той модели, которые были заданы.
Если разработчик забыл сформулировать важное правило, система его не проверит. Если неверно описано окружение или сделано неправильное предположение о поведении одного из компонентов, формально правильный результат тоже может оказаться мало полезным.
Поэтому такой подход не заменяет тестирование, анализ кода и инженерное понимание системы. Он добавляет ещё один способ проверки, который особенно полезен там, где можно достаточно точно сформулировать свойства, обязательные для выполнения.
Что мы хотим выяснить
По мере роста сложной системы всё труднее удерживать её правила только в головах разработчиков, документации и большом наборе тестов. Часть таких правил имеет смысл записывать в форме, которую можно не только прочитать, но и автоматически проверить.
В таком подходе исходный код отвечает за поведение системы, тесты проверяют выбранные сценарии, а формальная модель отвечает на другой вопрос: существует ли вообще допустимая последовательность действий, которая приведёт систему к запрещённому состоянию?
Именно для решения этой задачи мы экспериментируем с SJV. Сейчас для нас важно не доказать, что отдельный язык проверки подходит для всего, а определить границы его полезности: где он действительно упрощает разработку и обнаруживает ошибки, которые трудно найти обычными средствами, а где только добавляет системе ещё один уровень сложности.

 Share








